Mean time to detect measures the average elapsed time from a failure’s occurrence or discovery until the team able to fix it is notified and can engage. It evaluates the platform’s incident-detection path, not merely whether an alert exists. section 3.4.3
Measure MTTD by combining automated detection with effective escalation:
- Configure automated systems to watch relevant metrics, logs, or traces and trigger alerts. section 3.4.3
- Measure the interval from problem discovery to notification and engagement by the team with the most repair context. section 3.4.3
- Expand beyond known health indicators: monitoring specific problems is necessary but covers only part of failure management. section 3.4.3
MTTD is an early incident-response metric. Mean time to recover combines detection time with the time from detection to resolution, while incident detection time and mean time to acknowledge provide leading signals for improving monitoring and alerting. section 3.4.3 section 10.1.2
Figure 10.2 Key leading metrics used by Epetech to understand and use the DORA lagging metrics
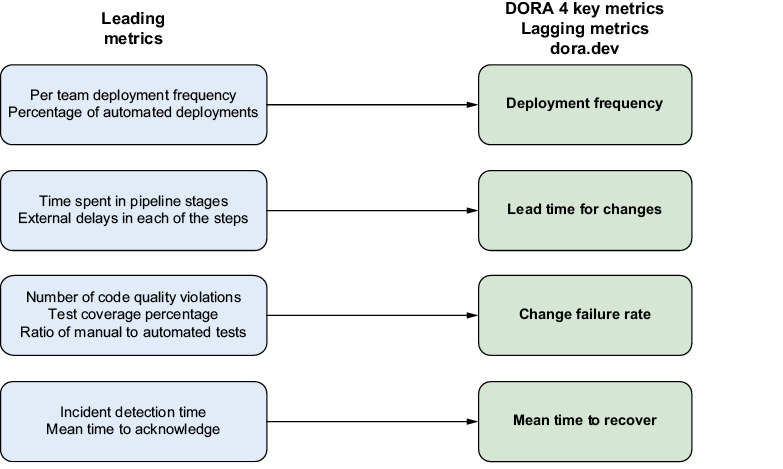
Use the leading-metrics figure to relate incident detection time and acknowledgement to broader platform and DORA measurement. section 10.1.2


