Mean time to recover (MTTR) measures the average elapsed time from failure detection through resolution and restored service. It combines mean time to detect with detection-to-resolution time; reducing it limits outage effects and improves availability and customer experience. section 3.4.3 section 10.1.2
Use MTTR alongside earlier incident-response and change-quality signals:
- Track mean time to detect and mean time to acknowledge to expose delays before resolution begins. section 10.1.2
- Pair recovery time with change failure rate to connect incidents with changes across development, quality assurance, preview, and production environments. section 3.4.3
- Measure rollback effectiveness and document suboptimal incidents with Correction of Error records, even when deployments are not classified as erroneous. section 10.1.2
Epetech’s measurement approach
Epetech used MTTR to assess how quickly service was restored after incidents, complemented it with detection and acknowledgement metrics, and connected these measures to developer productivity and operational efficiency. section 10.1.2
Figure 10.2 Key leading metrics used by Epetech to understand and use the DORA lagging metrics
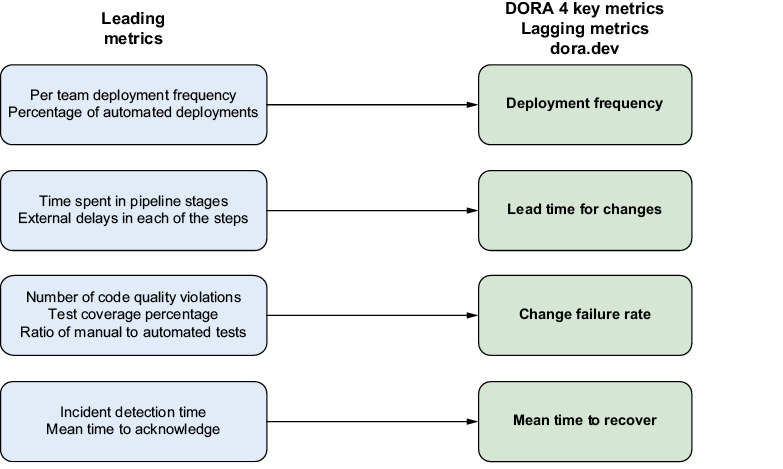
Use the leading-metrics figure to relate MTTR and incident-response signals to broader DORA outcomes. section 10.1.2




