An attention query is an embedding vector that represents what the model is looking for. It is compared with key vectors to decide which corresponding values should matter. section 3.2.2
Attention uses a query in a fuzzy lookup:
- The query represents the information sought. section 3.2.2
- The transformer compares it with all available keys rather than requiring one exact match. section 3.2.2
- More similar keys receive more influence through attention, which combines their associated values. section 3.2.2
Predicting the next token
When predicting the next token, the current token acts as the query. The model compares it with preceding words as keys, then uses the resulting attention pattern to produce a likely output. section 3.2.2
Figure 3.8 An example of how queries, keys, and values work inside a transformer compared to a Python dictionary. When a Python dictionary matches queries to keys, it needs an exact match to find the value, or it will return nothing. A transformer always returns something based on the most similar matches between queries and keys.
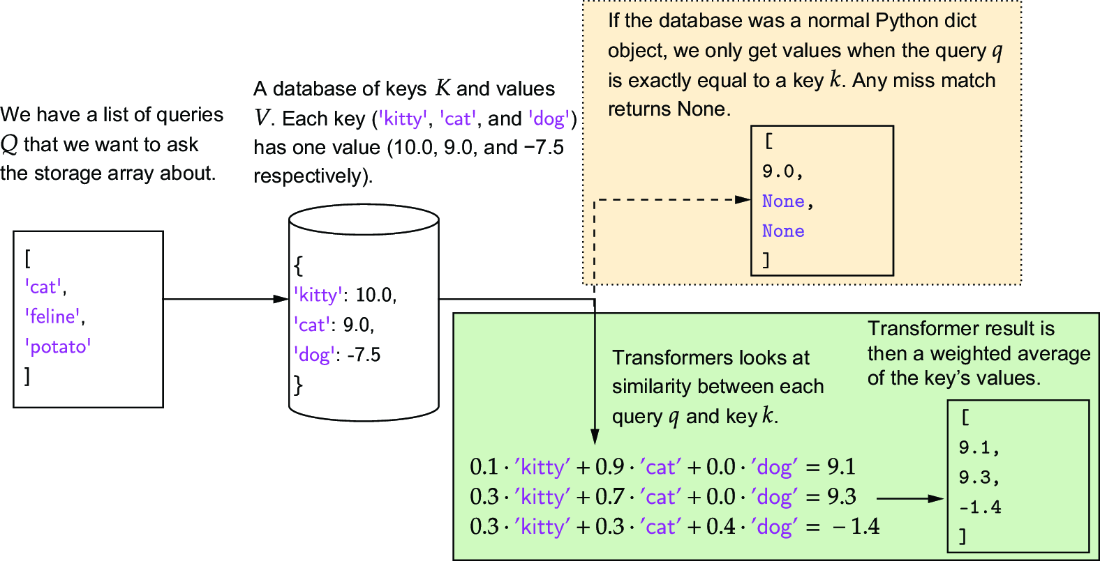
Compare attention with a Python dictionary: a dictionary needs an exact key, while attention returns a weighted result from approximate matches. section 3.2.2






