A query is a learned vector representation of a sequence position. In self-attention, it is compared with keys to score how relevant other positions are; the resulting attention weights combine their values. section 9.1.1 section 9.5
For an input embedding X, a neural layer produces Q. Comparing Q with K gives scaled attention scores; softmax turns these into weights, which are applied to V. This is scaled dot-product attention (SDPA). section 9.1.1 section 9.5
A library search
Searching for “machine learning in finance” supplies the query. Book titles and descriptions act as keys; books with closer matches receive higher scores and are recommended as values. section 1.3.1
Figure 9.1 A diagram of the self-attention mechanism. To calculate attention, the input embedding X is first passed through three neural layers with weights, WQ, WK, and WV, respectively. The outputs are query Q, key K, and value V. The scaled attention score is the product of Q and K divided by the square root of the dimension of K, dk. We apply the softmax function on the scaled attention score to obtain the attention weight. The attention is the product of the attention weight and value V.
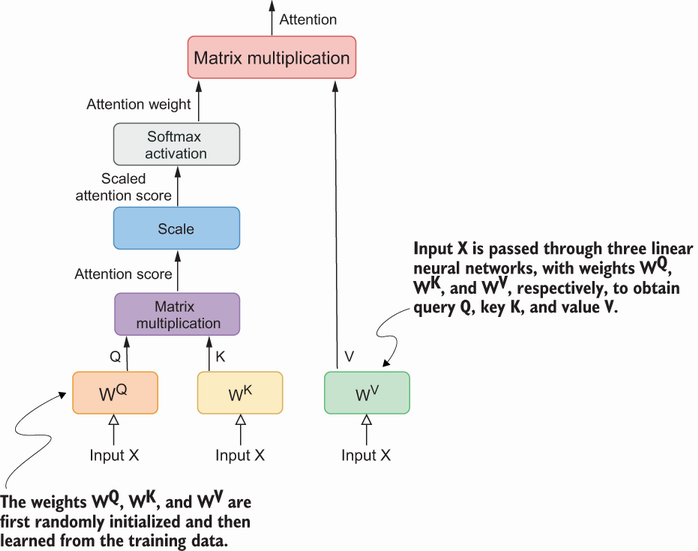
Trace how input embeddings become queries, keys, and values, then how scores and weights produce attention. section 9.1.1













