A query is an attention projection that represents what a sequence position seeks from other positions. In Transformer cross-attention, the decoder’s query interacts with encoder keys and values to score which encoded inputs matter for the next token. section 5.1
Decoder cross-attention
At each decoding step, a query compares against encoded input representations through keys, producing relevance scores whose weighted values form context for token generation. section 5.1
Figure 5.1 A simplified schematic of the Transformer architecture. The model consists of an encoder (left) and a decoder (right), each comprising repeated stacks of sublayers, including multihead attention mechanisms, feed-forward neural networks, and postprocessing steps such as residual connections and layer normalization. Positional encodings (depicted as circled crosses) are added to the input embeddings to explicitly represent token order. The diagram emphasizes the cross-attention operation (dashed box labeled “Cross-attention”), in which the decoder’s queries (Q) interact with the encoder’s keys (K) and values (V). During cross-attention, each decoding step computes attention scores to determine the relevance of encoded input representations, producing a context vector that guides token generation. This selective alignment enables the decoder to integrate contextual information from the encoder, improving the accuracy and coherence of the output sequence.
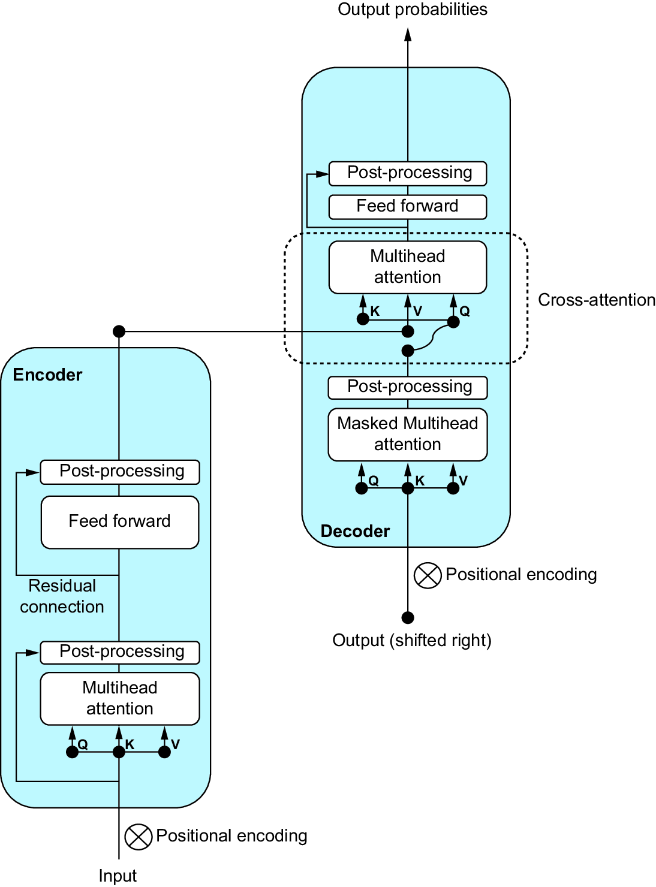
Use the Transformer schematic to trace how decoder queries interact with encoder keys and values during cross-attention. section 5.1






