A rectified linear unit (ReLU) is an activation function that keeps nonnegative inputs unchanged and turns negative inputs into zero: ReLU(x) = x for x ≥ 0, and ReLU(x) = 0 for x < 0. section 10.14
ReLU helps a neural network learn complex, nonlinear boundaries. Its derivative is 1 for positive inputs, making it a practical response to the vanishing-gradient problem. section 10.14 section 10.25
Apply the rule in three quick steps:
- Give a negative input such as −3; ReLU returns 0. section 10.14
- Give zero; ReLU returns 0. section 10.14
- Give a positive input such as 4; ReLU returns 4. section 10.14
ReLU inside neural-network models
A two-dimensional classifier uses hidden layers of 128 and 64 nodes, each with ReLU activation, followed by a two-node softmax output. Trained for 100 epochs, the model reaches 90% accuracy on the dataset. A housing-price regression model similarly uses ReLU hidden layers, but ends with one output node without an activation function. section 10.18 section 10.20
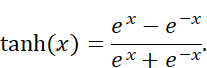
Inspect the piecewise equation to see exactly how ReLU transforms negative and nonnegative values. section 10.14















