A retry repeats a failed machine-learning workflow step, but helps only when the underlying failure is temporary or its prerequisites can be restored. section 6.3.2
Before rerunning a failed step:
- Identify the root cause, such as a lost network connection, insufficient computation, or an unavailable dependency. section 6.3.2
- Check whether required outputs still exist; restart data ingestion when training data was held only in lost memory. section 6.3.2
- Verify sufficient memory, CPU, and training workers before retrying model training. section 6.3.2
- Record runtime metadata, including data availability and resource usage, to support the decision. section 6.3.2
Training failure
When model training fails after an unexpected memory spike, inspect the recorded memory and data-availability metadata. Retry only after restoring adequate resources and confirming the training data; otherwise rerun ingestion first. section 6.3.2
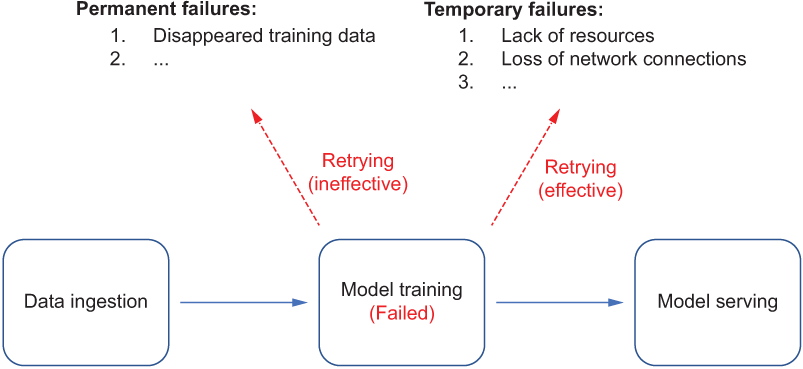
Compare retry effectiveness for temporary failures with repetitive failure under permanent conditions. section 6.3.2




















