A retry repeats a failed operation to recover from a transient failure. It is useful when a service makes synchronous calls, where delivery guarantees cannot be delegated to a message broker. section 10.2.5 section 8.2.4
In an HTTP-based saga, a communication failure leaves the orchestrator in its current state. After a timeout, it tries that state again. Make participant endpoints idempotent so a duplicate request can return the original response. section 10.2.5
Figure 10.16 The state machine for a saga orchestrator that invokes the participants using HTTP. HTTP responses trigger state machines. If there’s a communication failure, the state is unchanged and a transition to the same state occurs after a timeout.
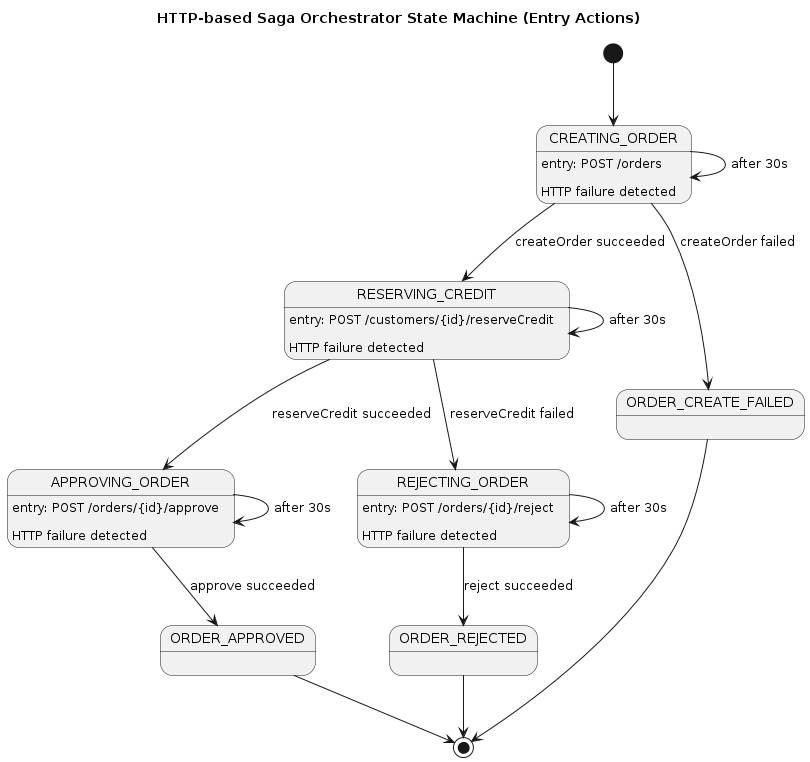
See how an HTTP communication failure keeps the saga state unchanged until a timeout triggers another attempt. section 10.2.5
Retries can also be applied to synchronous provider calls in API composition. They are one resilience option alongside circuit breakers, time limits, and bulkheads; use them as part of a broader strategy for unavailable or slow providers. section 12.3.3 section 8.2.4
























