Suppose a pipeline fetches website events and calculates daily user statistics. Running it by hand leaves gaps; scheduling makes Airflow start DAG runs automatically. A schedule specifies when runs are due, while task dependencies determine which tasks can execute within each run. section 3.1 section 1.2.3
Four DAG parameters control a time-based schedule:
- start_date sets when scheduling begins; optional end_date limits how long it continues. section 3.2
- schedule determines when runs are due. With schedule=None, the DAG runs only when triggered manually. section 3.2
- catchup controls missed past run times. Its Airflow 3 default is False; set it to True when historical runs are wanted. section 3.2 section 3.3.1
Run a daily pipeline at midnight UTC
Set start_date to January 1, 2025, end_date to January 5, 2025, and schedule=CronTriggerTimetable("0 0 * * *", timezone="UTC"). Add catchup=True if those dates are already past and their runs are needed. Without an end date, the schedule can continue indefinitely. Give each run a dated output path—for example, /data/events/{{ logical_date | ds }}.json—rather than letting successive runs overwrite one file. section 3.3.1
Choose the timetable by what a run means. A trigger-based timetable schedules a run as soon as possible after a specified point, much like cron. A data-interval-based timetable divides time into slots and runs after each slot ends. Its data_interval_start and data_interval_end identify the data to process, making it suitable for incremental loading; logical_date can identify the run. section 3.3.5 section 3.4.4
Figure 3.8 Time represented in terms of Airflow’s scheduling intervals, assuming a daily interval with a start date of 2024-01-01. Execution happens at the end of the interval (e.g., the DAG run for the first interval is executed at 2024-01-02 00:00).
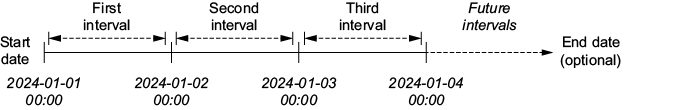
The daily-interval timeline shows why the run for January 1 executes on January 2: the entire January 1 data interval must finish first. section 3.4.4
For historical data, interval-specific runs can process past slots instead of reprocessing the full dataset. Catchup schedules missed past runs; clearing past task results also permits rerunning them after a code change. Prefer an explicit timetable class over a bare @daily or cron value when timing semantics matter: instance settings can change how shorthand is interpreted, and defaults changed between Airflow 2 and 3. Asset-based schedules are another option when time is not the trigger. section 1.2.5 section 12.1.7 section 3.2




