A key engineer decides to leave, and they are the only person who knows a critical service well. The team may struggle to keep work moving after their departure. That concentration of knowledge is a single point of failure: too much depends on one person being available. section 8.4.3
The risk can grow even when things are going well. Giving a high performer autonomy and challenging work supports their growth, but relying on them alone can turn them into a bottleneck. The Bus Factor is a related way to think about the risk of losing critical knowledge. section 4.4.2
Spread knowledge and responsibility before a departure forces the issue:
- Use lunch-and-learns, technical talks, and documentation to share critical-service knowledge. section 8.4.3
- Encourage high performers to mentor others while continuing to support their own growth. section 4.4.2
- When someone is unavailable, assign work to another informed team member; notice where the handoff reveals a bottleneck. section 5.3.1
- Check whether upskilling and knowledge sharing are happening, rather than judging team success only by delivery. section 3.2.7 section 9.2.6
If a departure is unavoidable, focus on a smooth transition and a balanced workload. Ask: which work would stall if one team member became unavailable, and who else could take it on? section 8.4.3 section 5.3.1
Figure 8.3 A sample offboarding checklist to use for a seamless transition when an employee departs the team
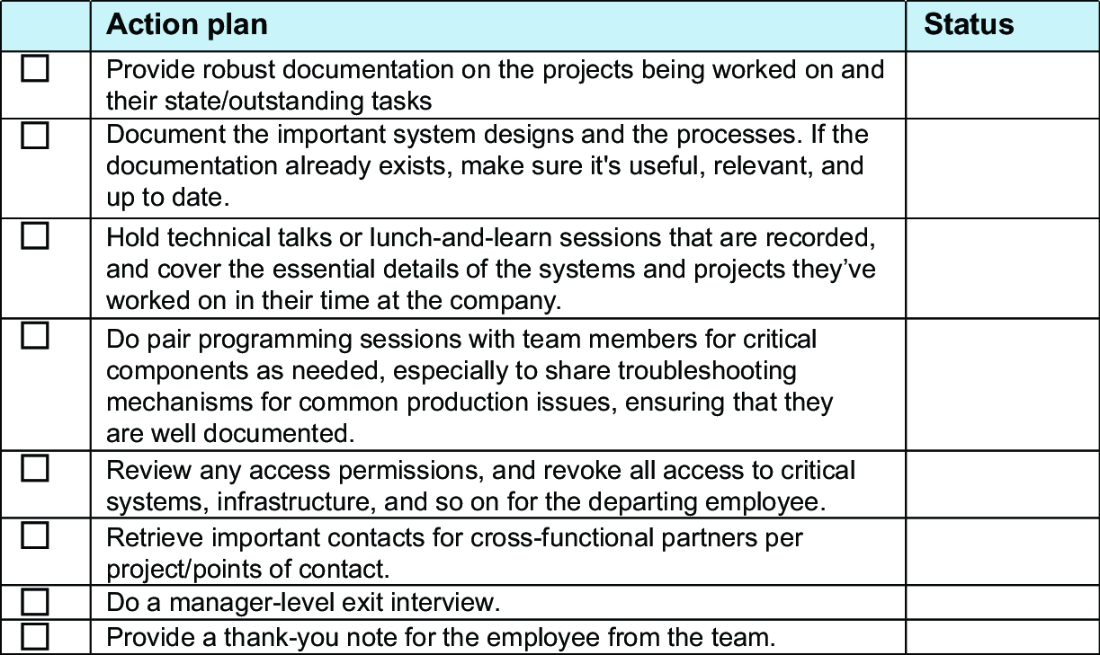
Use the sample offboarding checklist as a starting point when planning an employee’s transition. section 8.4.3



