When a model compares one token with all the others, it needs more than raw scores: it needs weights that show how much attention each token receives. Softmax turns those scores into nonnegative weights that add up to one. section 2.1.3
Turning relevance into attention
For the token "it" in "The performance was unbelievable — the crowd couldn't believe it," dot products produce relevance scores. Softmax converts them into weights such as performance → 0.72, crowd → 0.18, and couldn't → 0.06, with the remaining tokens receiving very little. The model then uses these weights to combine the tokens' value vectors. section 2.1.3
Figure 2.3 When processing "it," the model assigns an attention weight to every other token in the sentence. "Performance" receives the highest weight by far (0.68 out of 1.0)which is how the model infers what "it" refers to.
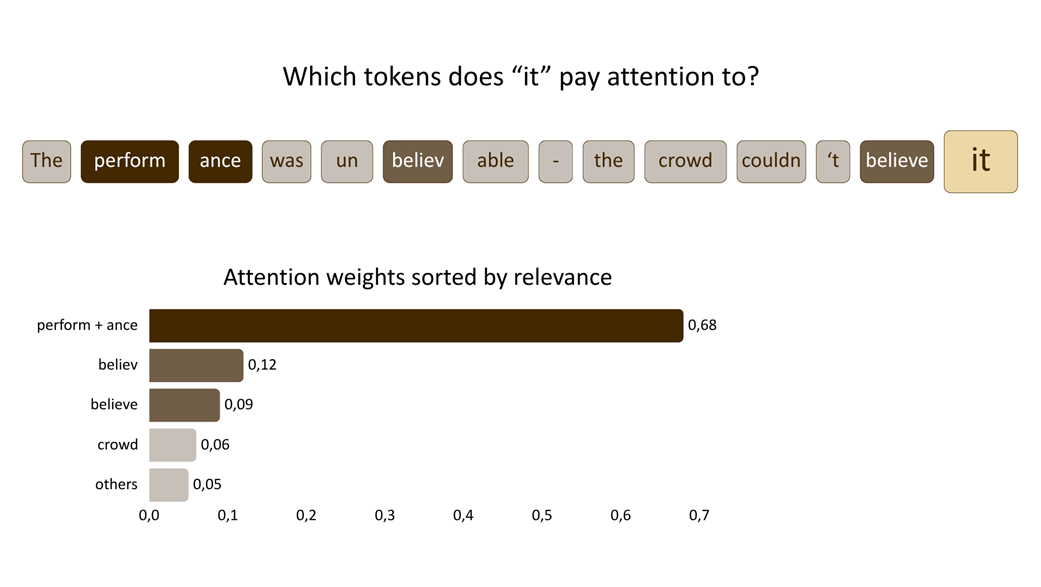
Visualizes how normalized attention weights distribute focus across every token while processing "it." section 2.1.3

























