liveBook · Manning

Video

As explained in Data Analysis with LLMs

Video data consists of sequences of visual frames, typically accompanied by motion and possibly audio.

Video data consists of sequences of visual frames and can be analyzed by language models for useful insights. A practical task is generating a suitable title from video content. section 1.2 section 6.0

A video-analysis request typically combines:

  • Selected video frames, submitted as images. section 6.4.1
  • A text instruction such as “Generate a concise title for the video.” section 6.4.1
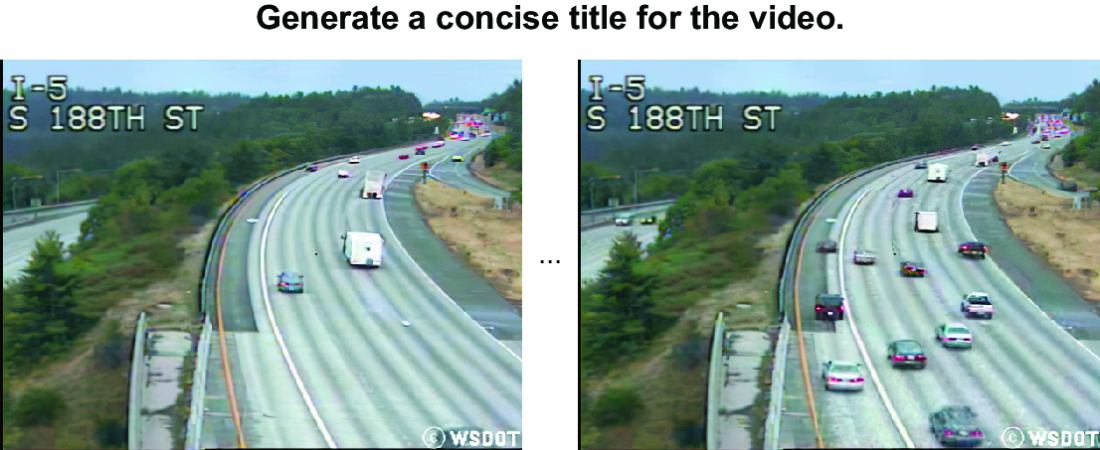
  • A generated output, such as a concise title describing cars or a visible location. section 6.4.1

Generating a video title

Send a selection of frames together with an explicit instruction to GPT-4o. The model can return a title based on visible subjects and text in the frames, but each submitted frame increases processing cost. section 6.4.1

Figure 6.3 Multimodal prompt for video processing: based on a selection of video frames, the language model is instructed to generate a suitable title.
figure

Use the prompt illustration to inspect how selected frames and a title-generation instruction form one multimodal request. section 6.4.1


How Data Analysis with LLMs covers it

How deep it goes
Explains frame-based multimodal prompting and cost implications, but stops short of implementation details for extracting frames.
Examples
Uses selected frames showing cars and possibly a location to demonstrate automatic title generation.
What it assumes
Requires understanding that videos can be represented through frames and analyzed alongside natural-language instructions.
What you can do after
Build video-processing applications that submit frames and instructions to generate suitable titles.
How it connects
Connects video with visual frames, multimodal prompts, images, and language-model analysis.

Also explained in

Compare how 5 books explain video →

Related concepts

This explainer was generated by Manning's knowledge graph from the text of Data Analysis with LLMs. The section links point to the parts of the book it draws on.


