A vulnerability is a weakness that can be exploited to produce unsafe outputs, leak user data, compromise systems, or create other undesirable consequences. In generative AI, vulnerabilities may arise from the model, its prompts, its tools, or the surrounding social and technical context. section 5.9 section 10.10
Red teaming finds vulnerabilities by simulating attacks. Testers create adversarial or difficult inputs, inspect responses, and look for recurring weaknesses before real attackers exploit them. Simple user-like interactions can be useful, while automated methods can generate and refine harmful prompts at greater scale. section 5.9
Common vulnerability patterns include:
- Out-of-distribution inputs can make responses less predictable and less influenced by safety fine-tuning. section 5.9
- Hypothetical scenarios or personas may conflict with safety guardrails and elicit unsafe assistance. section 5.9
- Poisoned datasets, prompt injection, and jailbreaks can alter behavior, bypass protections, or trigger harmful actions in tool-augmented systems. section 10.10
A vulnerability is not merely a technical bug. Harms emerge when weaknesses meet deployment choices, human behavior, institutions, infrastructure, and weak oversight. Scale can turn a model flaw into a societal harm, affecting privacy, trust, security, or other social outcomes. section 10.15 section 10.6
Figure 5.11 The red-teaming process for LLMs
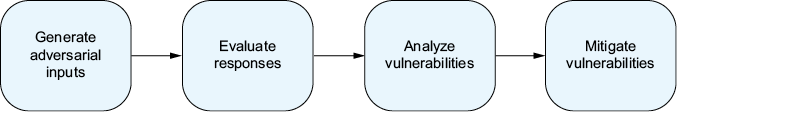
Use the red-teaming process to connect adversarial inputs, model responses, vulnerability patterns, and mitigation work. section 5.9















