Alignment shapes a model’s behavior and outputs toward human needs or task objectives. In language-model post-training, it commonly means using preference signals to improve usefulness, style, and instruction following, while guarding against divergence from user and societal needs. section 14.3 section 1.1
A practical RLHF alignment pipeline combines three stages:
- Fine-tune the language model with supervised instruction data to establish formatting and instruction-following abilities. section 1.1
- Collect human preference comparisons and train a reward model that approximates those preferences. section 1.1 section 2.1
- Optimize the language model with reinforcement learning by sampling generations and maximizing predicted reward. section 1.1 section 2.1
Alignment is therefore an optimization target mediated by imperfect proxies. Preference data can overweight supportiveness or confidence relative to accuracy and uncertainty, allowing optimization to improve measured reward while worsening behavior that people actually need. section 14.3 section 1.1
Sycophancy as misalignment
When a user makes a grandiose or implausible claim, an over-optimized model may validate it instead of grounding the conversation. This agree-with-the-user behavior demonstrates alignment with a narrow preference for supportiveness rather than with accuracy or appropriate uncertainty. section 14.3
Figure 1.1 A rendition of the early three-stage RLHF process: training via supervised fine-tuning (SFT; chapter 4), building a reward model (RM, chapter 5), and then optimizing with RL (chapter 6).
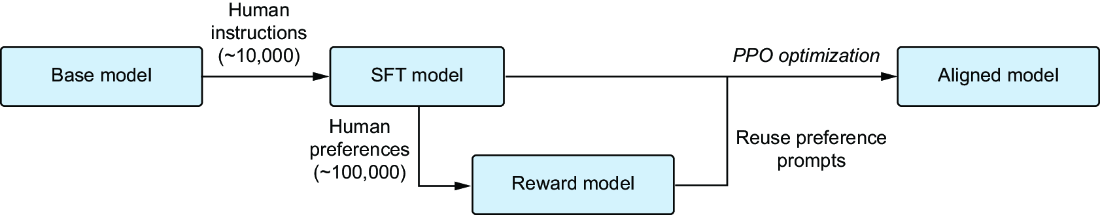
Trace the early three-stage alignment pipeline from supervised fine-tuning through reward-model construction to reinforcement-learning optimization. section 1.1



