In sequential learning, TD(0) offers fast updates, while Monte Carlo accounts for longer-term outcomes. The bias–variance tradeoff describes the balance between these approaches; TD(λ) makes it adjustable by averaging n-step returns. section 6.5
TD(λ) shifts the balance through λ:
- At λ=1, it is close to Monte Carlo; intermediate values, such as 0.7, blend the approaches. section 6.5
- Eligibility traces provide an online backward-view implementation, assigning more credit to recently visited states and letting older traces decay. section 6.5
Figure 6.7 Comparison of TD(0), Monte Carlo and TD(λ) methods.
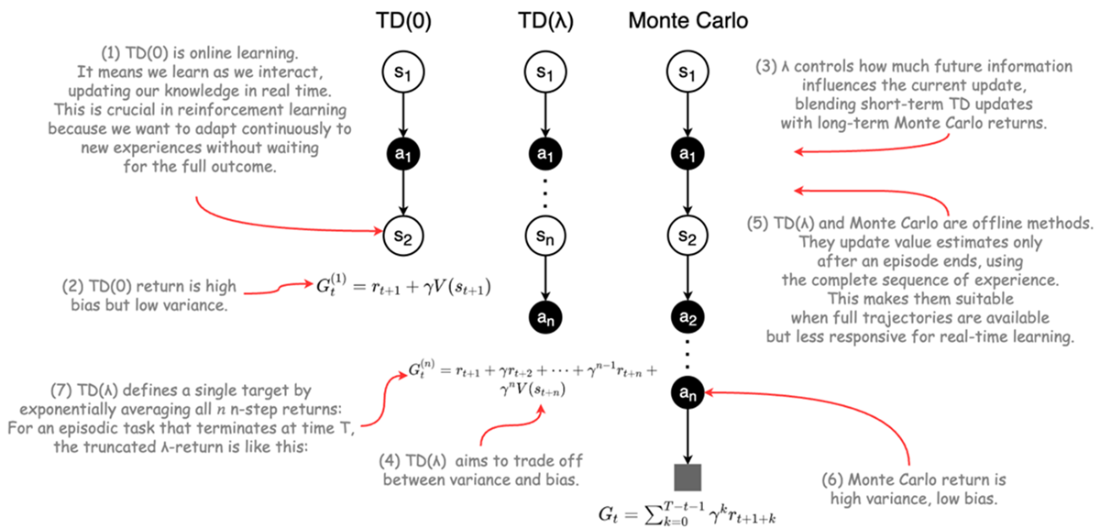
Compare TD(0), Monte Carlo, and TD(λ) to see the methods positioned along this tradeoff. section 6.5




