A cluster centroid is the representative mean vector of the items assigned to a cluster. In vector search, centroids partition a large vector space into groups of similar vectors. section 2.2.1
K-means constructs centroids through an iterative procedure:
- Initialize k centroids randomly. section 2.2.1
- Assign each vector to its nearest centroid. section 2.2.1
- Recalculate each centroid as the mean of its assigned vectors, then repeat until convergence. section 2.2.1
Centroids in approximate search
FAISS first compares an incoming query with cluster centroids, using only k comparisons. It then searches the selected cluster or clusters instead of exhaustively comparing the query with every vector, turning million-vector searches into thousand-vector searches. section 2.2.1
Figure 2.3 FAISS's Two-Stage Search Strategy.
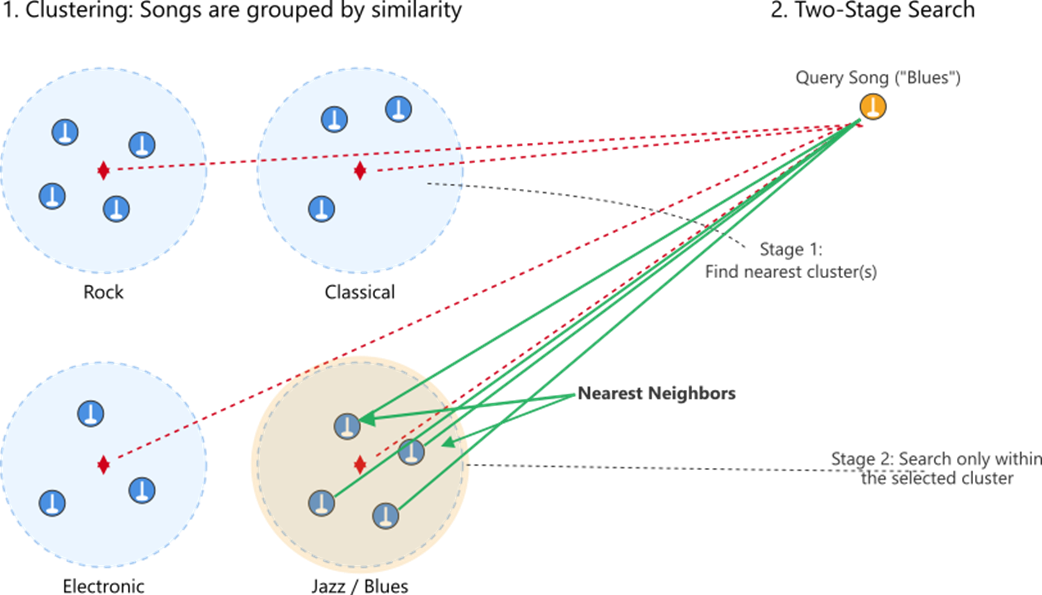
Shows FAISS's two-stage strategy: route a query through centroid comparisons before searching vectors within the selected cluster. section 2.2.1









