Hosted LLM APIs remove the need to manage GPUs and model updates, but they charge for usage. Cost can rise sharply when production requests are longer or more frequent than prototype requests. Estimate spending from real input and output lengths, not just short test prompts. section 10.2.1
A request that changes the estimate
A customer writes a detailed support request rather than a short question. One illustrated exchange uses 356 input tokens and 891 output tokens—1,247 tokens in all—and costs $0.32. Thousands of similarly verbose exchanges would make a short-prompt estimate misleading; the illustrated price is not a universal rate. section 10.2.1
Measure cost alongside the work that produced it. Request logs can record input and output tokens, model and prompt versions, latency, and spending. In one request-life-cycle comparison, inference accounts for $0.004193 of cost versus $0.00001 for other operations combined. That makes output length, prompt efficiency, and model routing more promising cost targets than infrastructure changes in that case. section 10.3.2
Figure 10.3 LLM request life-cycle timeline showing where time and cost are spent during a typical customer-support query. The figure reveals that LLM inference dominates both execution time (89.3%) and cost (97%), making model optimization the highest-value area for performance improvements.
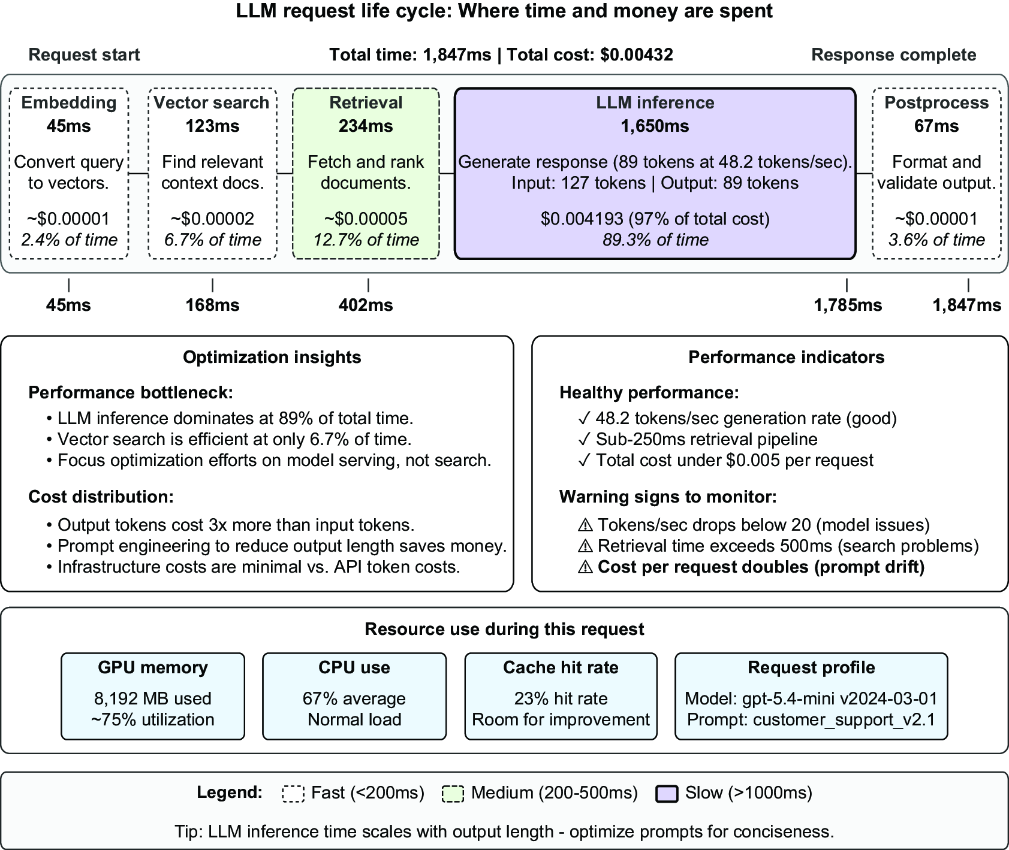
The request timeline compares component latency and expense, making the concentration of cost in inference visible. section 10.3.2
Treat spending changes as production signals, not just billing surprises:
- Compare current hourly cost with a historical baseline and alert on a large jump. section 10.3.4
- Watch trends and investigate changes in prompt length, traffic, model routing, or the complexity of user questions. section 10.3.4
- Trace token counts and cost through the pipeline when a request needs closer investigation; Langfuse provides this visibility alongside prompt, model, latency, and quality traces. section 10.6
A cost alert points to a change, not necessarily its cause. A prompt change once tripled a team's monthly bill by making responses longer; another issue routed every query to a more expensive model. Use request-level evidence to distinguish these failures before changing infrastructure. section 10.3.4 section 10.3.2









