A computer cluster is a group of networked computers that jointly processes large datasets. Distributed frameworks divide work across nodes, run tasks in parallel, and combine the results. section 11.2.3
Clusters address practical limits of single-machine and traditional warehouse processing:
- Reduce processing time by assigning manageable task portions to multiple nodes. section 11.2.3
- Improve fault tolerance by rerouting a failed node’s task to another node. section 11.2.3
- Require analysts to learn framework-specific SQL or libraries, such as Spark SQL or PySpark. section 11.2.3
- Demand cost controls because large-scale processing can consume substantial storage, node, and query resources. section 11.2.3
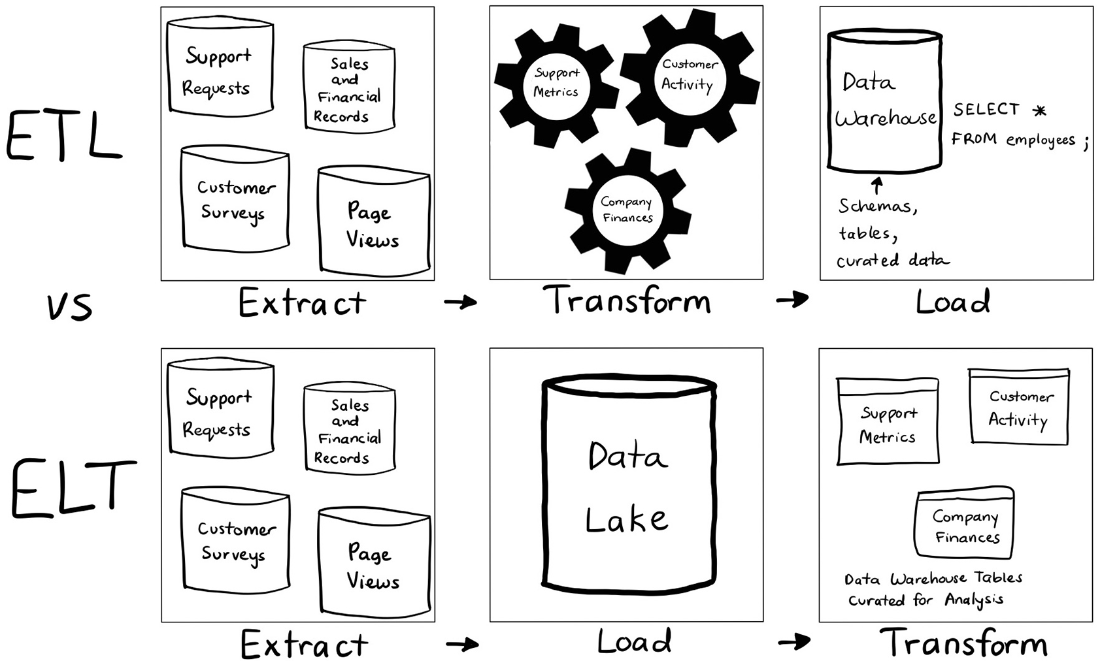
Figure 11.9 ETL and ELT processes transform the data at different steps, leading to structured data in the warehouse.
Use the parallel-processing figure to trace how a large task is divided across a cluster and recombined into one result. section 11.2.3







