Computer vision enables computers to interpret visual data and combine it with language. In an application, a user submits an image with a prompt, and a vision-capable model analyzes the image before generating a context-aware response. section 3.4.1
A typical vision request moves through these stages:
- Accept an image together with a text prompt. section 3.4.1
- Analyze visual content to recognize objects, text, and other relevant features. section 3.4.1
- Combine the visual information with the prompt to form an interpretation. section 3.4.1
- Generate an answer or other output based on the combined understanding. section 3.4.1
Diagnosing a broken appliance
A user uploads a photograph of a broken appliance and asks, “What is this part, and how do I fix it?” The model can identify the part, analyze its condition, and provide a detailed answer. section 3.4.1
Figure 3.7 The process of sending an image alongside a text prompt to the OpenAI API and how the language model utilizes computer vision techniques to understand the image and generate a relevant text response
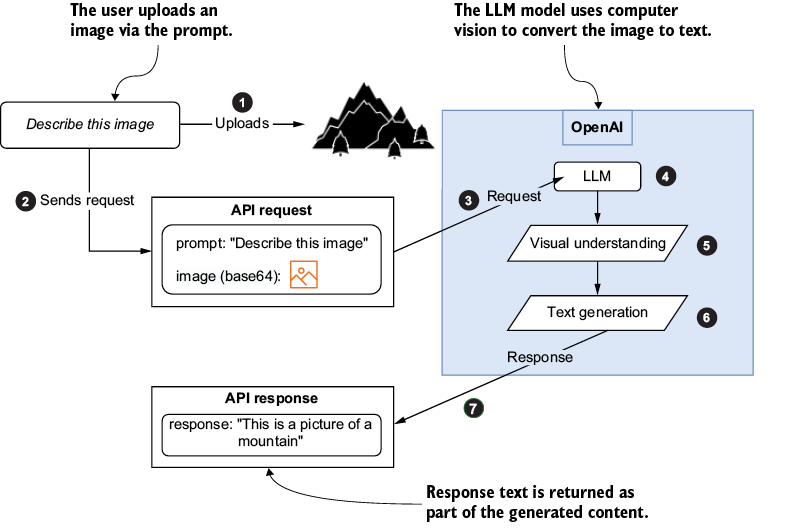
Trace how a client file input sends an image and text prompt to an LLM API, which forwards them to a vision-capable model for response generation. section 3.4.1







