A decoder-only transformer generates text autoregressively: each decoder block attends only to tokens generated so far, then predicts one next token. That token is appended to the running sequence and fed back in to continue generation until an end token appears. section 5.2.1
GPT uses this design for prompt-based text production. Unlike the original encoder-decoder transformer used for translation, it has no separate encoder and no encoder-decoder attention layer. Training on large text data teaches the model to predict the most likely next token from its preceding sequence. section 5.2.1
Tokens need not be whole words. Byte-pair encoding represents text as subwords, balancing the large vocabulary of word tokens against the long sequences created by character-level tokens. section 5.2.1
Figure 5.9 The Generative Pretrained Transformer (GPT) model architecture, and how it auto-regressively performs text generation.
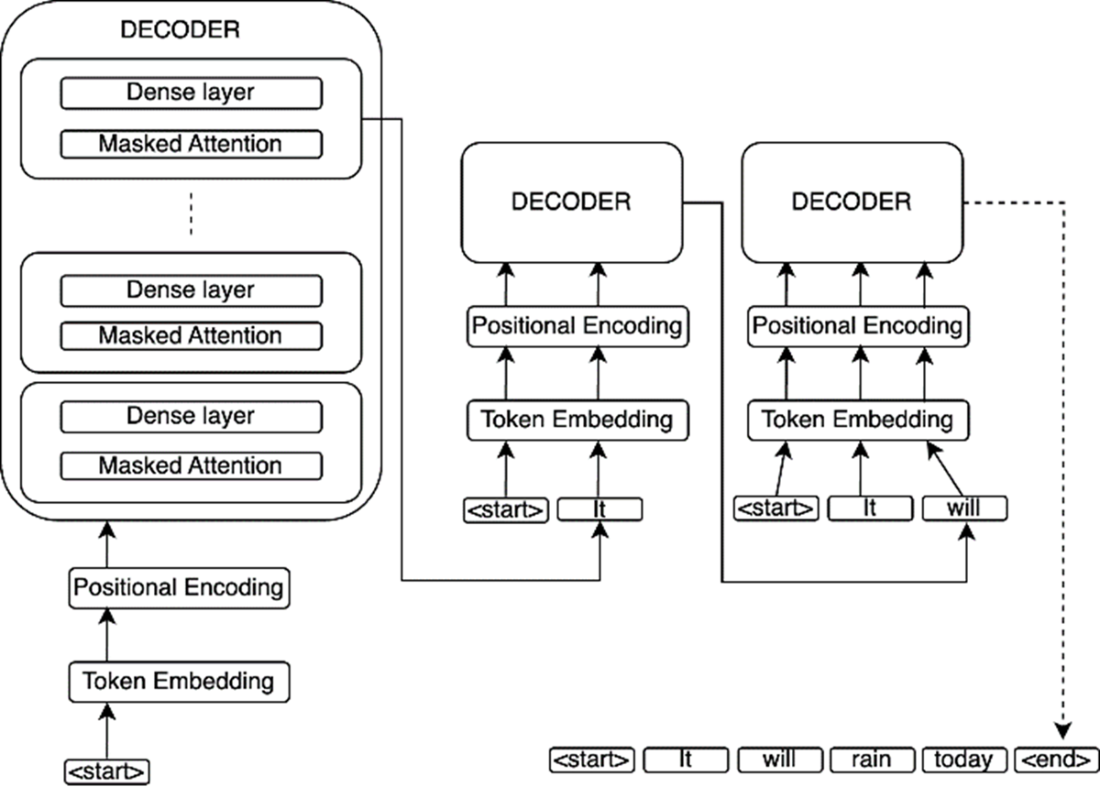
Shows the GPT decoder-only architecture and its autoregressive text-generation flow. section 5.2.1












