liveBook · Manning

Gemini

As explained in Generative AI in Action

Gemini is Google's multimodal AI model family for understanding and generating text, images, video, audio, and code.

Gemini is Google’s multimodal AI model for understanding text, images, video, audio, and code. It supports complex reasoning and code generation across multiple programming languages. section 2.1

Gemini’s role in the generative AI stack includes:

  • Processing and combining multiple information types rather than operating only on text. section 2.1
  • Supporting downstream specialization through fine-tuning or prompt engineering. section 2.1
  • Serving as Google’s umbrella name for AI tools that replaced Google Bard and Duet AI. section 2.1

Enterprise access

Developers can access Gemini through Google Cloud and Google AI Studio; API access was described as being in private preview at publication time. section 2.7.1

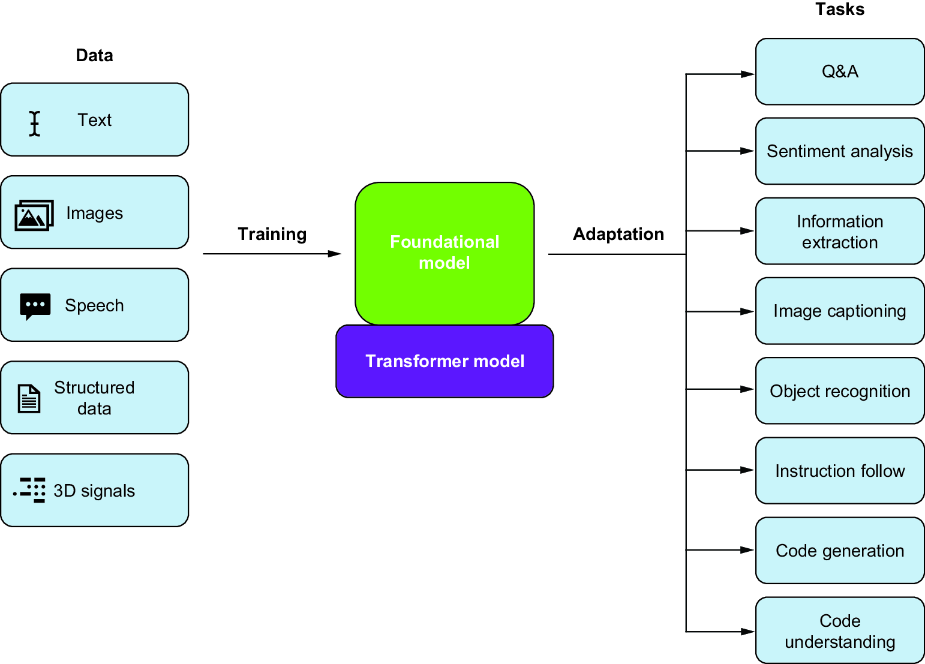
Figure 2.1 Foundational model overview
figure

Use the foundational-model overview to place Gemini among general-purpose models that can be adapted for downstream tasks. section 2.1


How Generative AI in Action covers it

How deep it goes
Explains capabilities, multimodality, branding, and adaptation options without detailing model internals or implementation mechanics.
Examples
Demonstrates text, code, images, video, and audio processing alongside mathematics, physics, reasoning, and programming tasks.
What you can do after
Evaluate/understand Gemini’s multimodal scope, adaptation paths, and Google Cloud or AI Studio availability.
How it connects
Connects Gemini with foundational models, PaLM, fine-tuning, prompt engineering, and Google AI Studio.

Also explained in

Compare how 7 books explain Gemini →

Related concepts

This explainer was generated by Manning's knowledge graph from the text of Generative AI in Action. The section links point to the parts of the book it draws on.




