K-means partitions vectors into a fixed number of similarity-based clusters, turning exhaustive nearest-neighbor search into a smaller staged search. section 2.2.1
The clustering procedure repeats four steps:
- Initialize k centroids randomly. section 2.2.1
- Assign each vector to its nearest centroid. section 2.2.1
- Recalculate each centroid as the mean of its assigned vectors. section 2.2.1
- Repeat until convergence. section 2.2.1
FAISS search
FAISS compares a query with cluster centroids first, then searches the selected cluster rather than every vector. This turns million-vector searches into thousand-vector searches. section 2.2.1
Figure 2.3 FAISS's Two-Stage Search Strategy.
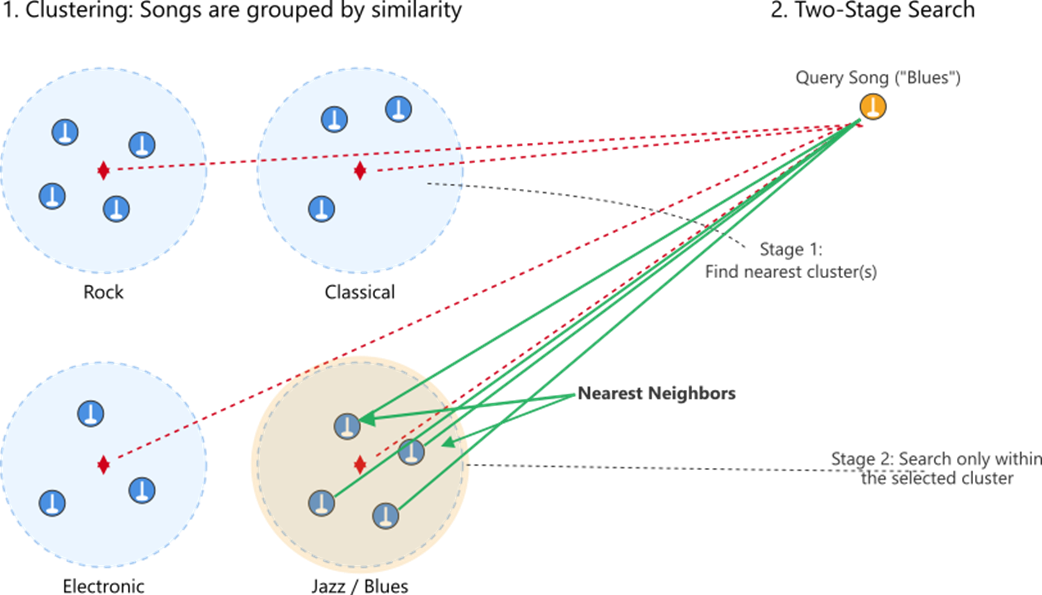
Shows FAISS’s two-stage strategy: route a query through centroids before searching vectors within the selected cluster. section 2.2.1











