Multi-head attention combines multiple self-attention layers. Each layer assigns attention coefficients to input time steps, allowing different layers to extract different signals from the same sequence. section 4.3.4
Within each self-attention layer, attention weights Pq, Pk, and Pv produce coefficients c1 through cn. These coefficients control how strongly each input element contributes to each output. The layer concatenates the outputs from its multiple self-attention layers into a richer feature representation. section 4.3.4
Figure 4.21 A multi-head attention layer showing the concatenation of features produced by multiple self-attention layers, producing a set of attention coefficients that inform the model to look at different parts of the input sequence in different proportions.
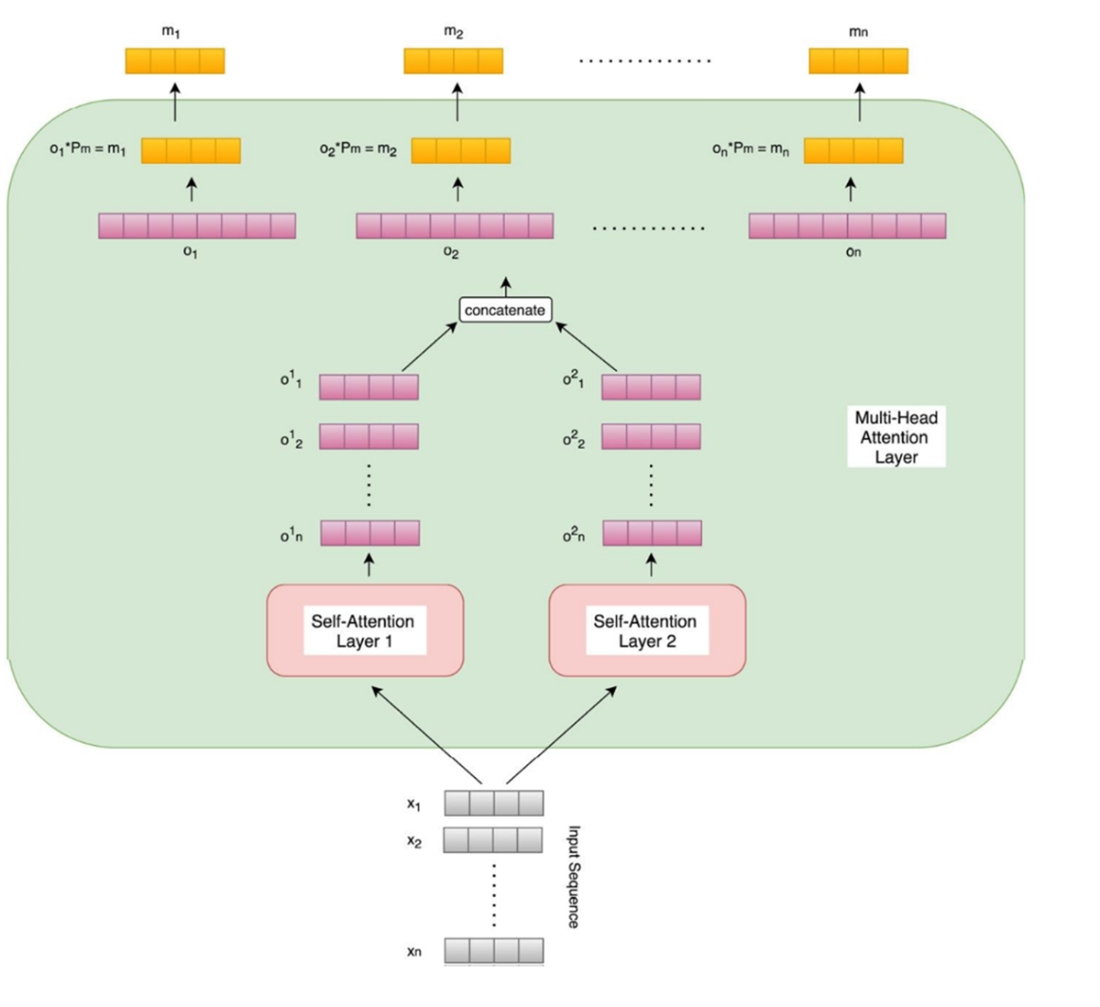
Shows how multiple self-attention outputs are concatenated and attend to different input-sequence elements in different proportions. section 4.3.4
























