Multi-head attention runs several attention operations in parallel. Each head can focus on different input parts, helping representations capture multiple relationships and patterns. section 11.3.2
In graph attention networks, each head can attend to neighboring nodes differently. Attention scores are commonly normalized with softmax; head outputs are then typically averaged before a final nonlinearity produces prediction probabilities. section 11.3.2
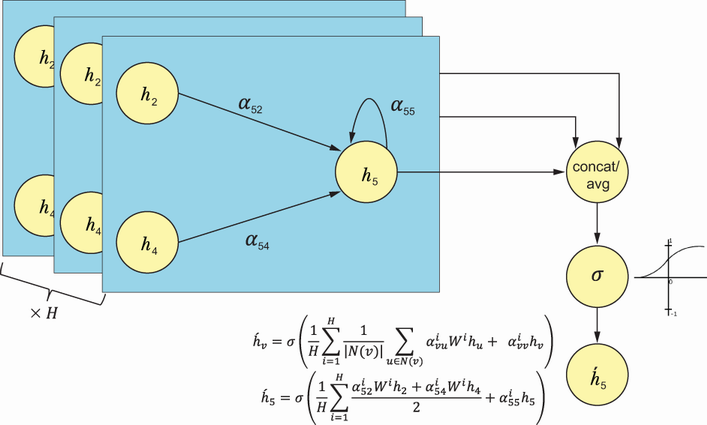
Three heads attending from node 5
With H = 3 heads, node 5 assigns attention coefficients such as α52, α54, and α55. Each head aggregates features differently, and the resulting embeddings are averaged into node 5’s final representation. section 11.3.2
Figure 11.10 Multi-head attention with H = 3 heads by node 5. α52, α54, and α55 are the attention coefficients between the nodes. The aggregated features from each head are averaged to obtain the final embedding of the node.
Inspect the three-head graph example and its averaged node embedding. section 11.3.2













