Multihead attention runs several attention mechanisms in parallel, producing independent output heads that are concatenated and transformed through a dense layer. This gives a transformer multiple ways to interpret the same input. section 11.3
Within transformer models, multihead attention connects to:
- Self-attention, where the model attends to elements within a sequence. section 11.3
- Encoder–decoder attention, where target queries attend to source keys and values during translation. section 11.3
- Positional encodings, normalization, dense layers, and residual connections surrounding the attention mechanism. section 11.3
Transformer text classification
A transformer classifier uses a Keras MultiHeadAttention layer alongside embeddings, pooling, normalization, dense layers, and training callbacks. section 11.3
Figure 11.11 Multihead attention
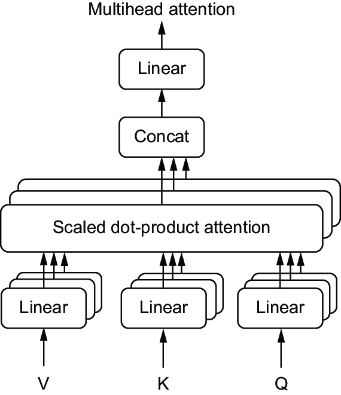
Use the multihead-attention figure to inspect how parallel heads are combined. section 11.3













