Stacking weighted sums alone cannot capture complex patterns: any number of linear layers collapses into one linear transformation. A nonlinear activation after each layer lets a network model more complex relationships. ReLU is commonly used in hidden layers, while linear outputs can represent Q-values. section 8.2
Figure 8.5 The building block of deep networks: neurons and activation functions
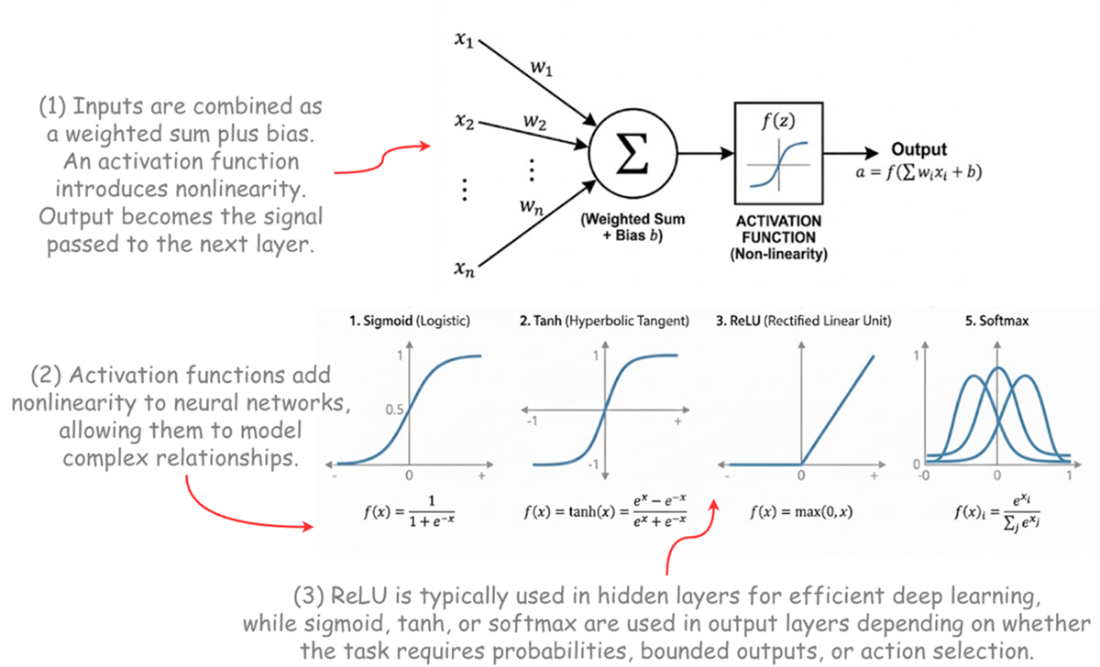
See how neurons combine weighted inputs with activation functions. section 8.2










