Ollama is a local application and serving wrapper for running large language models during inference. It wraps llama.cpp and supports command-line or API-based text generation, but not training or fine-tuning. section 7.8
A typical local workflow is:
- Start the application or run ollama serve in a separate terminal. section 7.8
- Download and run Llama 3 with ollama run llama3. section 7.8
- Send prompts through the local API at http://localhost:11434/api/chat, configuring the model, seed, temperature, and context length. section 7.8
- Use the model to score generated responses automatically against reference outputs. section 7.8
Automated evaluation
A Python workflow queries the local Llama 3 model with a prompt containing the instruction, correct output, and generated response, then requests an integer score from 0 to 100. The scores can be averaged across a test set. section 7.8
Figure 7.20 Two options for running Ollama. The left panel illustrates starting Ollama using ollama serve. The right panel shows a second option in macOS, running the Ollama application in the background instead of using the ollama serve command to start the application.
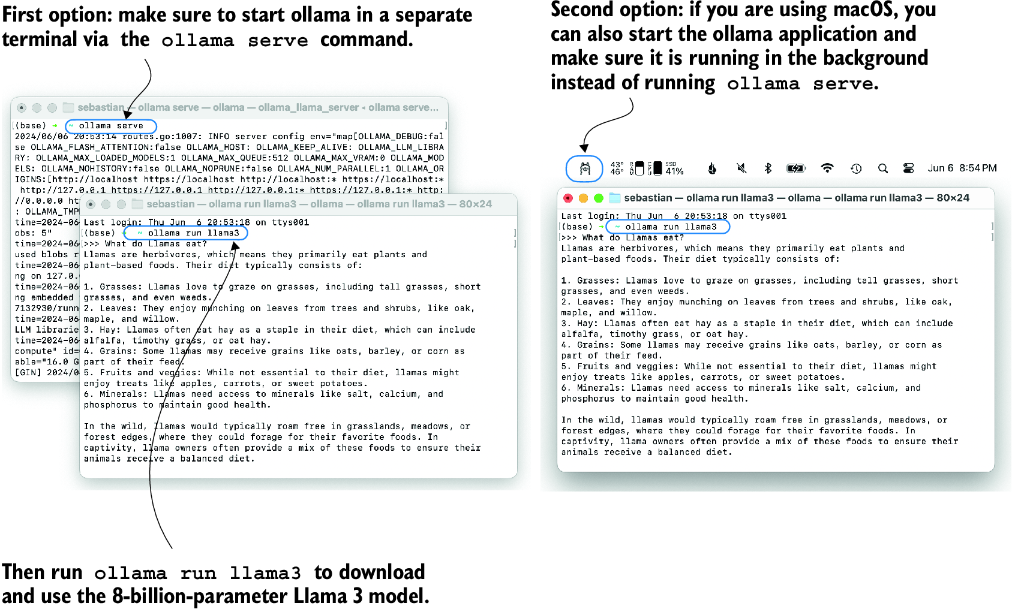
Compares starting Ollama with ollama serve and running the macOS application in the background. section 7.8







