Ollama packages models into lightweight bundles that run locally, keeping inference offline for privacy, lower latency, and control over outputs. section 2.2
A local Ollama workflow is:
- Create a Modelfile describing the base model and adapter. section 2.2
- Build and register the model locally. section 2.2
- Run the model interactively and offline. section 2.2
Private financial assistant
A Modelfile can reference llama2 and a finance adapter; `ollama create finance-model -f Modelfile` registers it, and `ollama run finance-model` starts local use.
Figure 2.2 LoRA adapter swapping for different domains or use cases. A single frozen foundation model serves as the shared backbone for multiple lightweight domain adapters. Each adapter adds a small set of trainable weights alongside the frozen layers — less than 0.1% of the base model's parameters — and can be swapped in or out without modifying the underlying model.
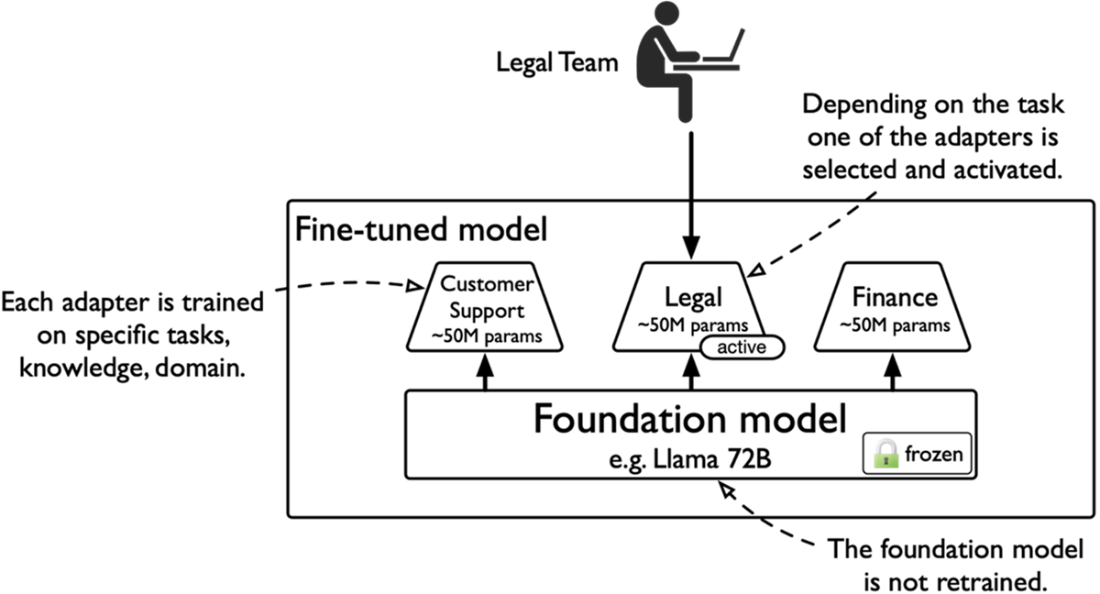
Shows how one frozen foundation model can support interchangeable lightweight adapters for different domains or tasks. section 2.2









