A query engine parses, plans, and executes queries against data sources. In an Iceberg lakehouse, it resolves table names through the catalog, reads metadata, plans file scans, and executes SQL across lakehouse or federated sources. section 7.1.2 section 8.7
A query engine coordinates several architectural responsibilities:
- Requests the latest table metadata from the catalog, including schema, partitioning, snapshots, and file manifests. section 7.1.2
- Uses file statistics and metadata for data skipping and predicate pushdown, reducing unnecessary scans. section 7.1.2
- Coordinates writes by committing new metadata and snapshots through an atomic catalog update, preventing conflicting operations. section 7.1.2
- Enforces query-time controls such as row- and column-level security while working with catalog policies. section 4.3.3
- Exposes interfaces such as JDBC and ODBC so BI tools, reporting applications, and spreadsheets can query lakehouse tables. section 9.3.1
Local Iceberg lakehouse
A Docker Compose environment uses Dremio as the SQL query engine, Nessie as the catalog, MinIO as object storage, Spark for ingestion, PostgreSQL as the operational source, and Superset for dashboards. Spark writes Iceberg data and metadata to MinIO; Dremio uses the same catalog and storage configuration to browse datasets and serve BI queries. section 3.2.3 section 3.2.4
Distributed query engines such as Trino divide analytical work into queries, stages, tasks, and splits that execute in parallel across coordinator and worker nodes. In federated environments, they push filters toward sources, reduce data movement, and isolate workloads through configurable resources or multiple clusters. section 8.3.7
Figure 7.4 Engines request tables from catalogs, and the catalogs return the metadata locations.
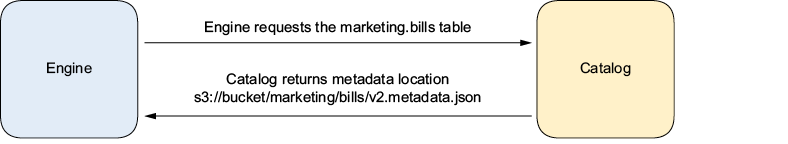
Use the catalog-to-engine flow to trace how a table name becomes a metadata location and then a planned data scan. section 7.1.2


