A query engine transforms submitted queries into computed results. DuckDB processes queries through an SQL parser, query execution planner, and query runtime; its vectorized engine processes data chunks in parallel for efficient use of multicore CPUs. section 1.1
Use the engine to:
- Analyze files and pipeline data without persisting them in DuckDB, including JSON, CSV, and Parquet sources. section 5.8
- Filter, aggregate, convert types, flatten JSON, enrich data through joins, and encapsulate transformations with views. section 5.8
- Query pandas DataFrames directly through SQL or a relational API, then retrieve results as cursors or DataFrames. section 6.3
Query a pandas DataFrame
Create a DataFrame named people with name and country columns, then run `SELECT * FROM people WHERE country = 'Germany'`. The result contains Michael Hunger and Michael Simons. A parameterized query can select people outside Germany and return the result with `fetchdf()` for continued pandas analysis. section 6.3
Figure 1.2 A high-level overview of DuckDB’s query-processing pipeline
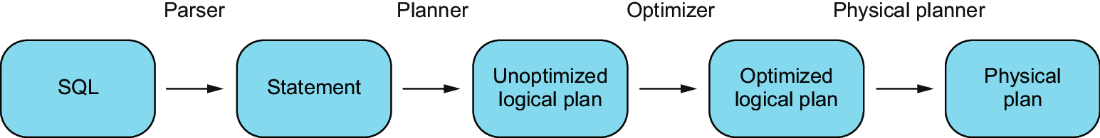
Follow the high-level query-processing pipeline from submitted SQL through parsing, planning, and runtime execution. section 1.1


