A reconstruction loss measures how closely a model-generated reconstruction matches the original data or representation. It gives self-supervised models a target without requiring manually labeled examples: reconstruct the missing or encoded information as accurately as possible. section 16.4.2 section 17.1.2
Use reconstruction loss to:
- Train foundation models to recover data from a partial representation, supporting later specialization for downstream tasks. section 16.4.2
- Train a variational autoencoder alongside a regularization loss: reconstruction preserves input content, while regularization shapes the latent distribution. section 17.1.2
Reconstructing an image with a VAE
An encoder maps an input image to latent variables, a latent point is sampled, and a decoder produces a reconstructed image. Reconstruction loss pushes that decoded image toward the original; the accompanying regularization loss encourages a well-rounded latent distribution. section 17.1.2
Figure 17.3 An autoencoder: mapping an input x to a compressed representation and then decoding it back as x’
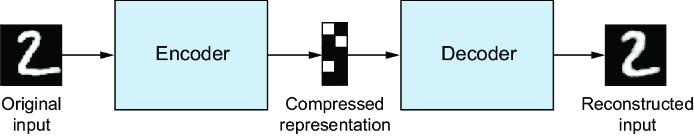
Trace the basic autoencoder path from input x through a compressed representation to reconstructed output x′. section 17.1.2









