U-Net is an encoder-decoder CNN that turns an image into a smaller abstract representation, then rebuilds a full-size image using features from the shrinking path. section 1.31
Repairing or restyling an image
A U-Net can reconstruct a damaged image or transform an ordinary picture into a different style, such as a Van Gogh-like painting. section 1.31
The shrinking path applies convolutions and downsampling to capture abstract content. A second CNN-like path extracts intermediate feature maps and stitches them together to recover the original image size. section 1.31
In conditional diffusion, a U-Net-like model receives a noisy image plus a text embedding and learns to repair the image. Repeating that repair from random noise produces a caption-guided image. section 1.32
Figure 1.11 A diffusion model is trained to improve a corrupted image paired with its caption.
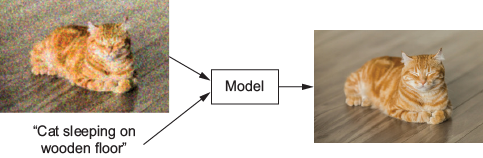
Use the figure to visualize supervised training on corrupted images paired with captions and clean targets. section 1.32




