Backpropagation trains neural networks by pushing calculated loss backward through the network. It is the conventional alternative to evolutionary parameter search. section 6.1 section 6.2
The treatment positions backpropagation as a baseline for comparison:
- Gradient descent and Adam optimize the network after loss is propagated backward. section 6.2
- Neuroevolution removes train and back_prop functions, replacing gradient-based updates with direct weight assignment from genetic-algorithm individuals. section 6.2
- Automatic differentiation and backpropagation suit continuous problems, while evolutionary optimization is presented for discontinuous problems. section 6.6
A simple MLP baseline
A NumPy multilayer perceptron trains on generated classification, moons, circles, blobs, or Gaussian-quantile datasets, then reports predictions and accuracy. The circles dataset provides a more difficult test than the simpler examples. section 6.1
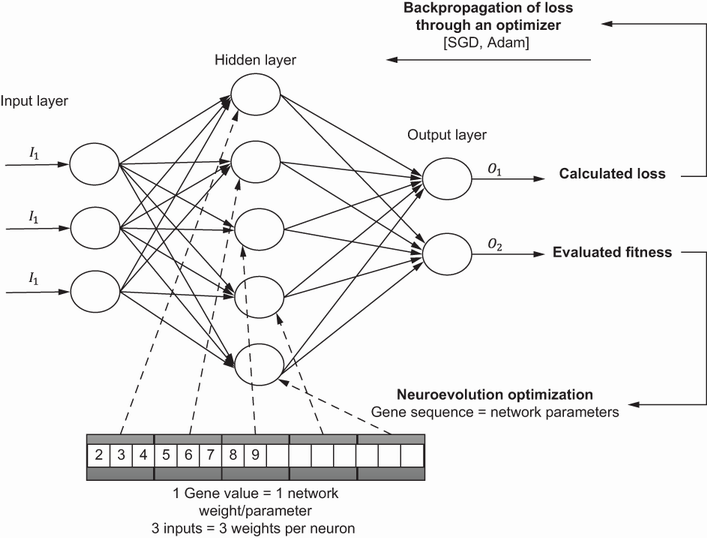
Compare the diagrammed flow of loss through an MLP with neuroevolution’s replacement of network weights. section 6.1
















