When a chatbot change produces a surprising result, a baseline shows whether performance actually improved, declined, or stayed the same. It is the reference measurement taken before the change, used with a corresponding post-deployment measurement. section 1.3.2 section 3.1
Use a baseline as part of a controlled improvement cycle:
- Measure current performance before changing training data, intents, dialogue copy, or process steps. section 1.3.2
- Connect the measurement to a meaningful problem, such as frequent transfers to an agent or low process completion. section 1.3.2
- Make one focused change, deploy it, and record its effect against the original measurement. section 1.3.2
- Repeat, investigate unexpected results, and undo changes that make performance worse. section 1.3.2 section 3.1
Baseline accuracy
Suppose a test set contains annotated user utterances and the chatbot’s original predictions or answers. Count the correct predictions or answers, divide by the total judged candidates, and record the resulting accuracy as the baseline. After retraining one poorly performing intent, compare the new accuracy with that reference rather than relying on impressions. section 4.5 section 4.6
Figure 1.9 A continuous improvement lifecycle for conversational AI
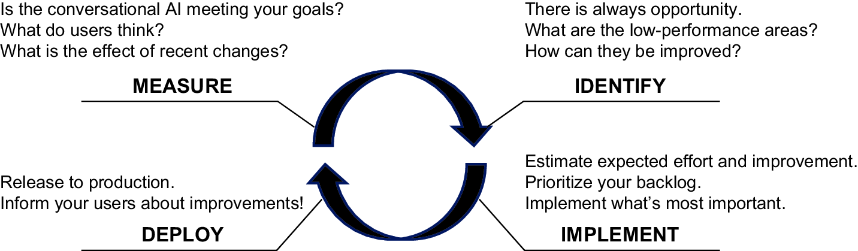
Use the continuous improvement lifecycle to connect baseline measurement with problem identification, implementation, deployment, and repetition. section 1.3.2















