Categorical data records which class an observation belongs to, rather than a measured amount. City, payment mode, product category, and a yes/no outcome are categorical; revenue and height are quantitative. A categorical variable can be binary (two mutually exclusive classes), nominal (classes without an order), or ordinal (classes with an order). section 1.2.2
Categories can be inputs to an analysis or the outcome to predict. Predicting whether a transaction is fraudulent or genuine is a classification problem; predicting a continuous amount is a regression problem. Before modeling, check what the categories mean and whether their values provide useful variation. A city field dominated by one value, or a zip-code field with nearly every value distinct, may add little to an analysis. section 1.5.1 section 11.6
Some algorithms need numeric inputs. K-means clustering, for example, calculates distances between data points and cannot directly use category names. One-hot encoding converts each distinct category into a separate column marked 0 or 1. For a city field containing London and New Delhi, that means two added columns. If it contains 100 cities, it means 100 mostly zero-filled columns; grouping some values may be more practical. section 2.7
Figure 2.36 Using one-hot encoding to convert categorical variables into numeric ones
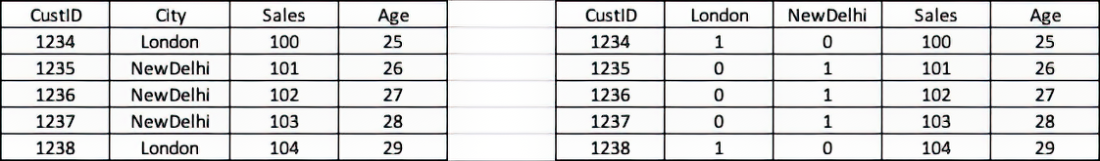
The figure shows how a city category becomes numeric indicator columns. section 2.7
Prepare categorical inputs in Python
In a mushroom dataset, inspect the shape and first rows before encoding categorical values. One workflow applies scikit-learn’s LabelEncoder to each column, separates features from the edible-or-poisonous class, scales the features with StandardScaler, and passes them to NumPy’s SVD. The shown LabelEncoder code assigns numeric labels; it does not create the separate indicator columns used in one-hot encoding. For one-hot columns, pandas provides get_dummies(). section 3.6.1 section 11.6 section 2.7















