Confidence is the probability an LLM assigns to each next token in a candidate answer. Scoring these probabilities estimates how strongly the model supports the complete sequence. section 5.4
Compute confidence as a sequence-scoring workflow:
- Convert the prompt into token IDs and run the model to obtain logits for every vocabulary token. section 5.4
- Apply softmax, select the probability of each observed next token, and multiply those conditional probabilities into a joint sequence probability. section 5.4
- Interpret consistently high token probabilities as stronger model support, while low probabilities signal a less compatible candidate. section 5.4
Comparing candidate answers
For “The capital of Germany is Berlin,” the demonstrated joint probability is 5.9372e-08; replacing Berlin with Bridge lowers it to 1.0481e-13. section 5.4
Figure 5.11 Computing token probability scores for a given sequence. For each position, we feed the preceding text into the model and read off the softmax probability of the next token. Multiplying these conditional probabilities yields the joint probability of the full sequence.
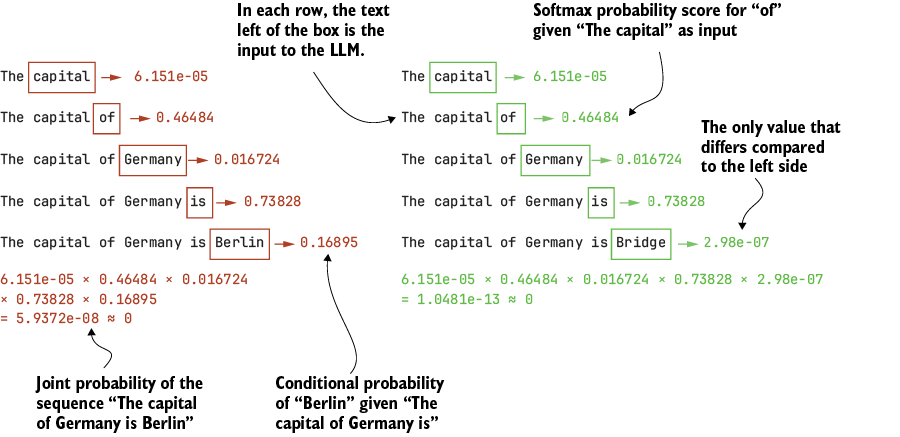
Shows how conditional next-token probabilities combine into a full-sequence probability. section 5.4