liveBook · Manning

Cross entropy loss

As explained in Natural Language Processing in Action, Second Edition

Log loss is a probabilistic prediction metric based on the negative logarithm of the probability assigned to the observed target.

Binary cross-entropy measures how well predicted probabilities match binary targets. Its logarithmic penalty makes confidently wrong predictions especially costly. section 5.2.5

Name classification

For a model predicting whether a name is labeled female, binary cross-entropy can weight each example by the name’s frequency in the dataset. section 5.2.5

Equation 5.2 Binary cross-entropy
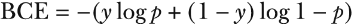
figure

Inspect the binary cross-entropy equation for a single classification probability. section 5.2.5

>>> loss_func_train = torch.nn.BCELoss(
...     weight=torch.Tensor(df[['count']][istrain].values))
>>> loss_func_test = torch.nn.BCELoss(                          #1
...     weight=torch.Tensor(df[['count']][~istrain].values))
>>> loss_func_train
BCELoss()

See PyTorch’s BCELoss configured with dataset-frequency weights. section 5.2.5

How Natural Language Processing in Action, Second Edition covers it

How deep it goes
Explains the logarithmic penalty for confident errors and shows frequency weighting and a PyTorch implementation.
Examples
Uses name-based sex classification and weights examples by their dataset frequencies.
What you can do after
Apply PyTorch BCELoss with frequency weights to train a sigmoid-output binary classifier.
How it connects
Connects sigmoid activation and binary classification to optimization with stochastic gradient descent.

Also explained in

Compare how 19 books explain cross entropy loss →

Related concepts

This explainer was generated by Manning's knowledge graph from the text of Natural Language Processing in Action, Second Edition. The section links point to the parts of the book it draws on.
















