The curse of dimensionality describes how many machine-learning procedures become exponentially more expensive as the dimensionality of the object of interest increases. In Bayesian optimization, estimating the distribution of an objective function’s optimizer requires exponentially more samples as the input vector grows. section 6.2.1 section 6.4
Optimizer location versus optimal value
Entropy search tries to model the optimizer x*, the input location where the objective reaches its maximum. Its distribution is complicated and increasingly costly to approximate in higher dimensions. A practical alternative targets the optimal value f* = f(x*), which is always one-dimensional; Max-value Entropy Search uses this reformulation to reduce the burden. section 6.2.1 section 6.4
Figure 6.11 The GP belief (top left), the distribution of the function optimizer x* (bottom), and the distribution of the optimal value f* (right). The distribution of the optimal value is always one-dimensional and, therefore, easier to work with than that of the optimizer.
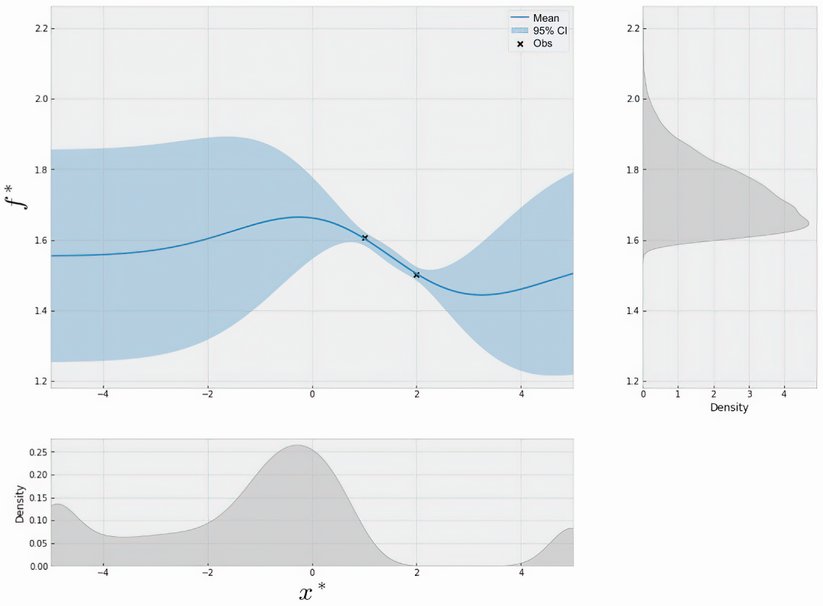
Compare the complicated distribution of the optimizer x* with the one-dimensional distribution of the optimal value f*. section 6.2.1






