Data integration combines data from cloud environments, SAS applications, and on-premises stores into usable structures for machine-learning work. Security requirements may keep sensitive data on premises rather than moving everything into the cloud. section 5.4
Treat integration as an engineered delivery task:
- Ingest data into the target infrastructure and processing engines. section 5.4
- Clean data, create features, and choose between a single modeling table or reusable intermediate tables and stores. section 5.4
- Provide controlled access through IAM and a serving interface such as SQL, files, or APIs, with documentation for self-service. section 5.4
- Checkpoint statistical risks from combining sources and prevent technical debt through disciplined pipeline engineering. section 5.4
Figure 5.1 The processing requirements delivered using the dev environment data pipeline infrastructure. This provides the data resources for the ML modeling team in sprint 2 and beyond.
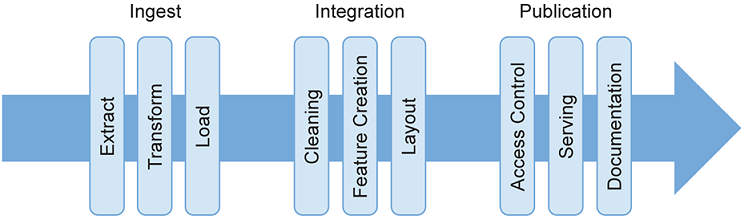
Maps the development-environment pipeline infrastructure that delivers data resources to the modeling team from sprint 2 onward. section 5.4




