Feature selection separates model inputs from the prediction target, then limits unsuitable or unwieldy inputs before training. The workflow also removes null-valued columns and rows with extreme prices so broken or high-leverage data does not distort predictions. section 4.5.4
A practical preparation sequence includes:
- Split the dataset into X, containing features, and y, containing the price label. section 4.5.4
- Remove columns whose values are null when the training procedure requires complete inputs. section 4.5.4
- Control categorical cardinality by retaining the top 50 Salt_Name values and grouping the remainder under Other_Salt before one-hot encoding. section 4.5.4
- Keep outlier removal distinct from feature selection: filter prices above the 99th percentile to reduce broken or disproportionately influential observations. section 4.5.4
Figure 4.7 One-hot encoding of the Salt_Name column value.
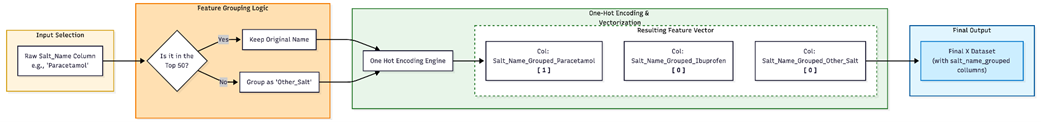
Inspect how one-hot encoding represents retained Salt_Name categories while collapsing less frequent values. section 4.5.4










