liveBook · Manning

Hidden layer

As explained in Grokking Machine Learning

A neural-network layer positioned between the input and output layers whose units transform intermediate representations.

A hidden layer sits between a neural network’s input and output layers. Its units form intermediate stages, and successive layers can combine simpler classifier boundaries into more complex ones. section 10.1

A two-layer classifier

For circular-data classification, one Keras model uses 128 and 64 units with ReLU activations, dropout between the hidden layers, and a two-unit softmax output. section 10.3

Figure 10.21 The architecture that we will use to classify our dataset. It contains two hidden layers: one of 128 and one of 64 nodes. The activation function between them is a ReLU, and the final activation function is a softmax.
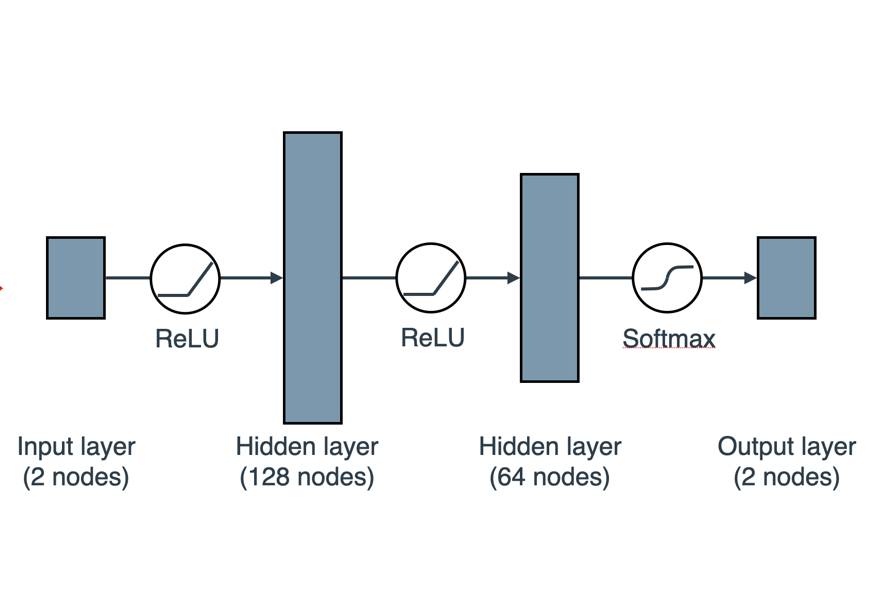
View the architecture diagram showing the two hidden layers and their sizes. section 10.3


How Grokking Machine Learning covers it

How deep it goes
Defines layer placement and sizes, then illustrates how successive layers combine classifier boundaries into more complex ones.
Examples
Uses an alien-classification example and Keras models for circular data and handwritten-digit recognition.
What you can do after
Apply hidden layers via Keras Dense layers, choosing sizes and activations for a classifier architecture.
How it connects
Connects hidden layers to neural-network architecture, perceptrons, classifiers, activation functions, and dropout.

Also explained in

Compare how 8 books explain hidden layer →

Related concepts

This explainer was generated by Manning's knowledge graph from the text of Grokking Machine Learning. The section links point to the parts of the book it draws on.




