In LLM generation, the model produces a probability distribution over possible next tokens; sampling picks one token from it. The model’s prediction and the decoding strategy that selects a token are separate steps. section 2.1.1
Generation settings shape the selection and its limits:
- Temperature, top-p, presence penalty, and frequency penalty affect which token is picked. Max tokens instead caps the response length. section 2.1.3
- Treat these settings as influences, not guarantees. Tune either temperature or top-p rather than both, and use max tokens to limit response length. section 2.1.3
Match settings to the role
A coder agent might use temperature 0 and a low frequency penalty for consistent output; a creative writer agent might use temperature 2 and a high presence penalty to encourage new ideas. section 2.1.3
Figure 2.3 The various parameters that can be used to modify an LLM’s output. The right side of the figure provides an expanded view of the model predicting and sampling tokens to generate output. On the left, we see the various parameters that can be used to alter the sampling of the next token within the model.
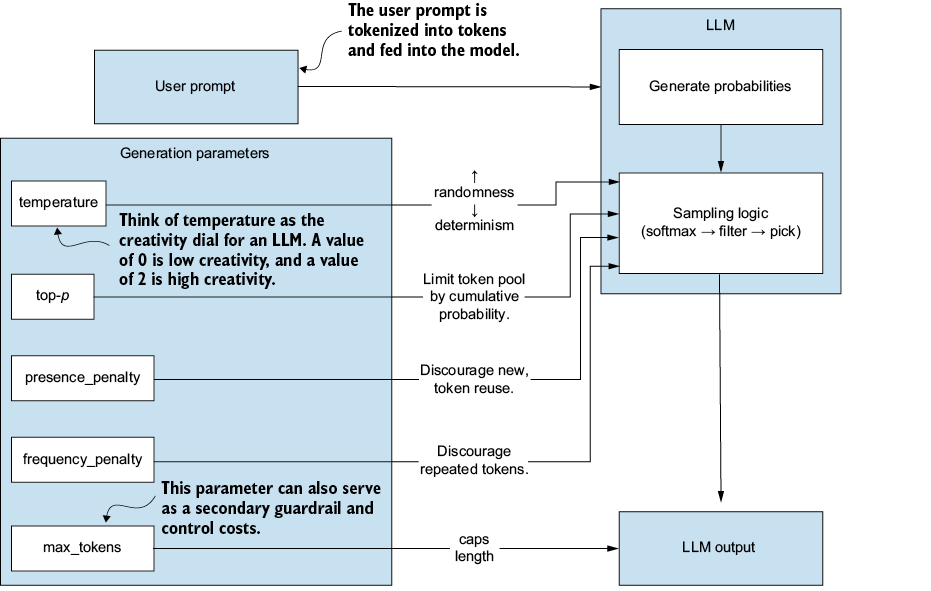
Trace how sampling parameters alter the next-token selection. section 2.1.3






















