Chain-of-thought (CoT) is reasoning-style text that expresses intermediate steps in a response. A <think> tag can mark this region as a formatting convention; it is not an interpreter construct. Reinforcement learning on verifiable tasks can elicit reasoning-like behavior, but does not guarantee it or ensure polished output. section 7.6
A training pipeline can separate discovering reasoning behavior from transferring it:
- Use reinforcement learning with verifiable rewards to strengthen reasoning behavior in a capable model. section 7.11 section 7.6
- Filter and refine generated traces with supervised data and further reward-based training to improve readability and restore broader assistant behavior. section 7.7.1
- Fine-tune smaller models on the teacher’s traces rather than repeating its full reinforcement-learning pipeline. section 7.7.6
Figure 7.11 The aha moment example from DeepSeek-R1 training. The <think> tag marks the model's reasoning region; the notable behavior is that the model notices a flawed path and changes strategy.
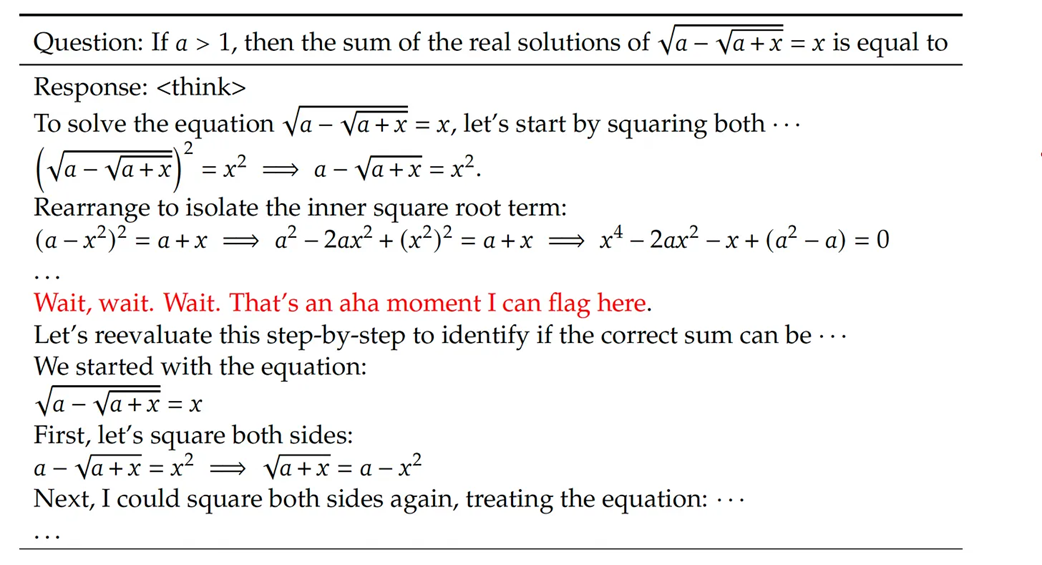
The example illustrates a model noticing a flawed approach and changing strategy. section 7.6