Reliability is the ability of an ingestion system to survive failures, retries, and interruptions without losing data, creating inconsistent table states, or undermining downstream analytics. Its requirements must be matched to delivery latency, source behavior, and business tolerance for reprocessing. section 6.1 section 6.1.2
Reliable ingestion depends on several coordinated mechanisms:
- At-least-once delivery can duplicate records after failure; exactly-once processing requires a replayable source and deterministic rereading. section 6.1.2
- Checkpointing coordinates state, offsets, and commits so failed work can be retried without exposing partial changes. section 6.1.2
- Iceberg atomic, snapshot-based commits keep incomplete writes invisible, but ingestion tools must still coordinate retries and prevent conflicts or duplicates. section 6.1.2
- Storage integrity also requires durability, replication, recovery, and synchronized restoration of Iceberg data files and transactional metadata. section 5.1.3
Figure 6.3 By using checkpointing to track which incoming records have been committed successfully, the system knows which records to retry when a failure occurs.
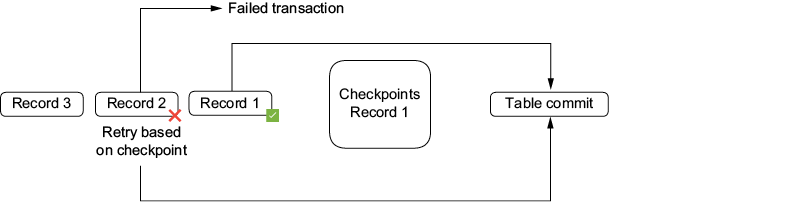
Checkpointing records which incoming records were committed, identifying the records that require retry after failure. section 6.1.2












