A token is a word or word part represented by a numerical index in a language model’s vocabulary. Tokenization breaks text into these units; the model predicts possible next-token indices, and a sampling step selects one to generate. section 2.1.1 section 2.1.2
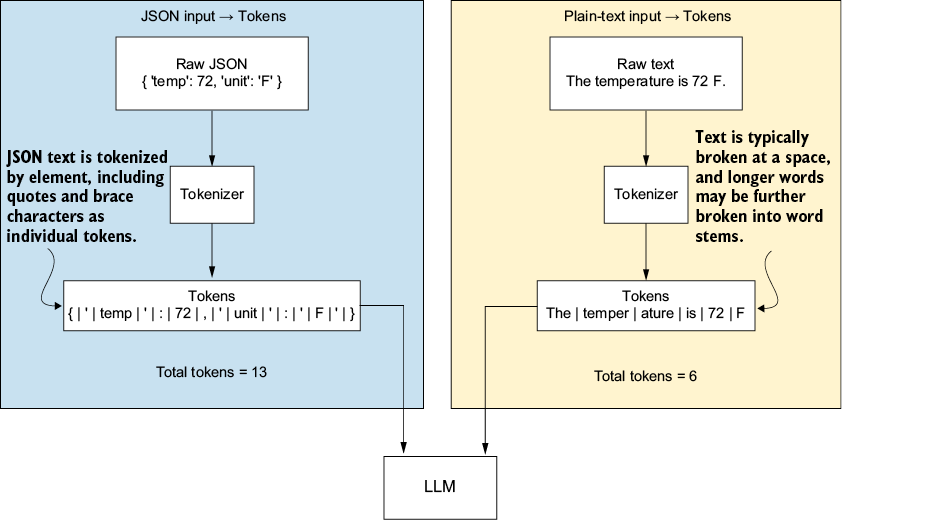
Text length does not reliably indicate token count. Punctuation, quotes, and field names in JSON can increase the count, affecting the cost of sending data to a model. section 2.1.2
JSON and regular text
A JSON block and equivalent regular text are shown as 13 and six tokens, respectively. Measure text with tiktoken or use token counts reported by the OpenAI Agents SDK; providers price input and output tokens separately. section 2.1.2 section 2.6
Figure 2.2 A comparison of tokenization in regular text and JSON
Compare how regular text and JSON are split into tokens. section 2.1.2






























