A token is a discrete piece of text that a tokenizer can count. Tokens may be words or n-grams, and can include punctuation, emoticons, and Chinese characters. Counting token occurrences turns text into a numerical representation that machine-learning systems can use. section 2.0
A bag-of-words representation assigns tokens to vocabulary slots and counts them, much like sorting coins into bins. It keeps the counts but loses word order, which can make the original sentence hard to understand. section 1.5.3
Treating every token as a separate vocabulary term has limitations:
- Ignoring token sequences loses co-occurrence information. section 2.3
- Treating related forms such as “swim” and “swimming” as different tokens can weaken tasks such as finding relevant articles. section 2.3
Figure 1.5 Canadian coin sorter
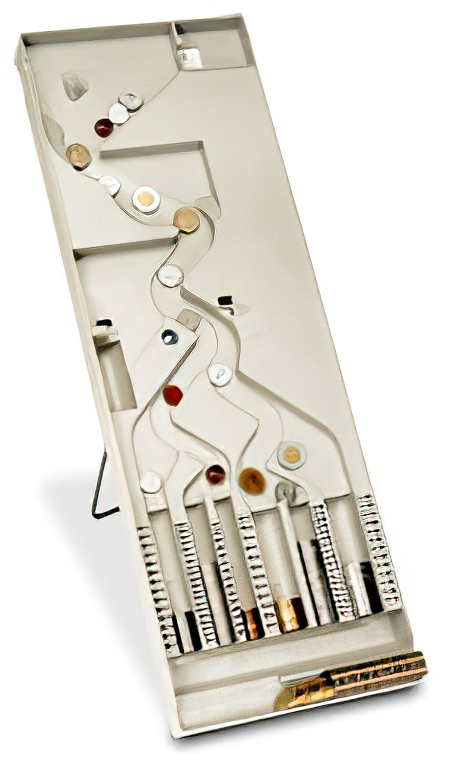
The coin sorter illustrates how tokens can be sorted into bins before their counts are represented as a vector. section 1.5.3






























