Transformer architecture is the foundation of large language models (LLMs), enabling efficient text processing and generation through learned patterns in extensive textual data. Training commonly uses next-word prediction, allowing models to capture grammar, context, associations, and some reasoning behavior. section 1.1
This architecture supports instruction-following outputs such as structured responses or creative writing, but it does not guarantee current, factual, or private knowledge. Retrieval-augmented generation (RAG) supplies external facts when the model's internal knowledge is insufficient. section 1.1 section 1.5
Next-word prediction
Given “Never gonna,” an LLM may generate “give you up,” demonstrating how training data provides associations that guide sequence completion. section 1.1
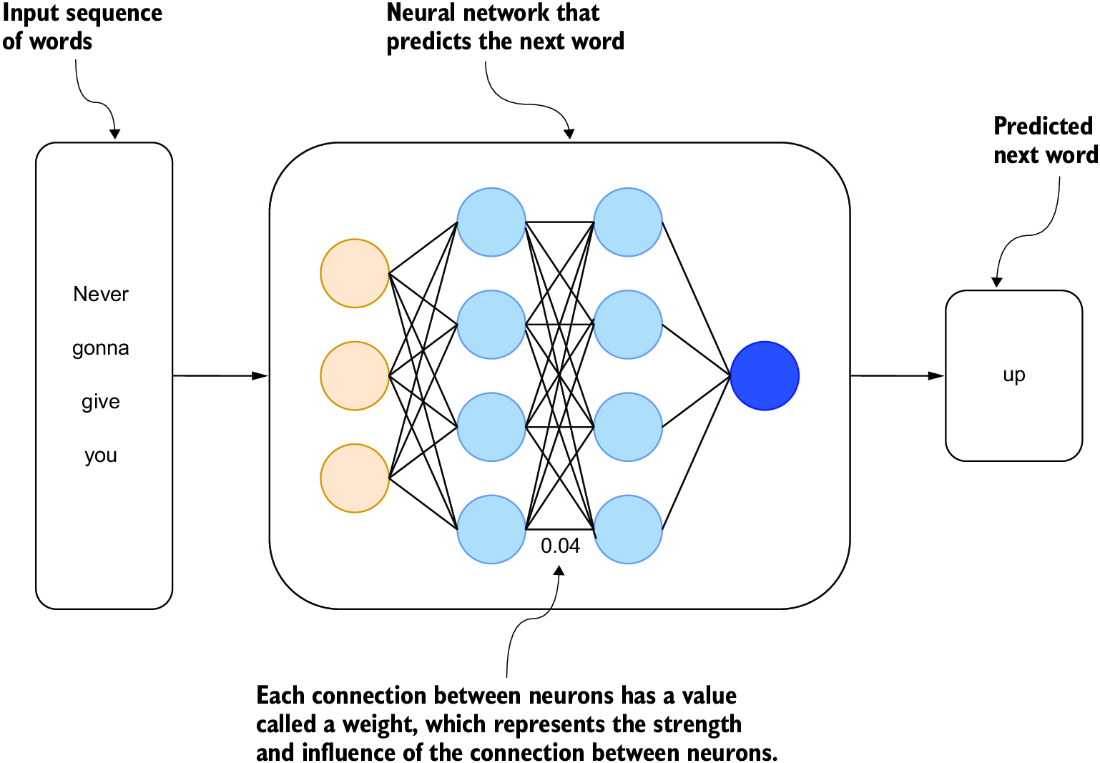
Visualizes a neural network predicting the next word from an input sequence. section 1.1



























