A transformer is a neural-network architecture for sequential data, especially text. It uses attention to relate elements of an input sequence, helping the model focus on the most relevant words while accounting for their positions. section 1.6
A useful mental model is a layered sequence-processing system:
- Represent the input as tokens and embeddings. section 1.7
- Process those representations through layers of interconnected neural-network nodes. section 1.6
- Use attention to emphasize relationships between the most relevant parts of the sequence. section 1.6
- Generate text one token at a time after large-scale pretraining. section 1.7
Predicting a capital
For “What is the capital of Italy?”, attention can emphasize “Italy” rather than words such as “what” or “is”, supporting the prediction “Rome.” section 1.6
Figure 1.11 How a GPT architecture generates sentences
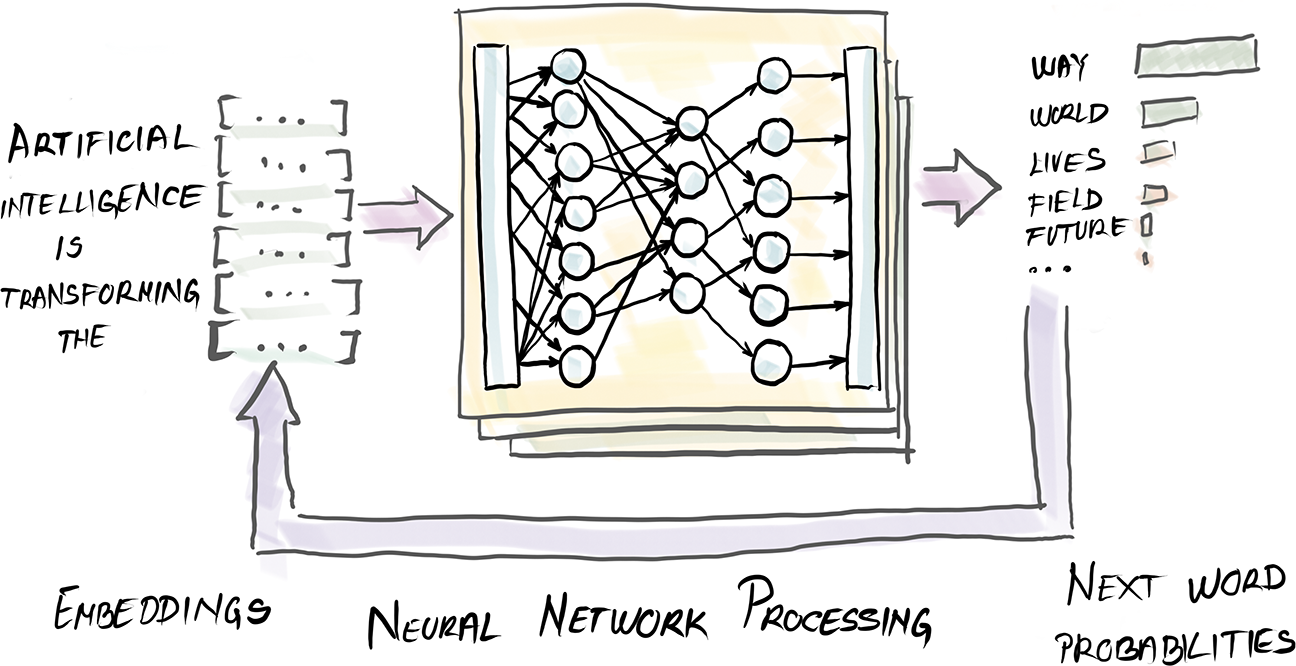
Use the architecture diagram to trace how a GPT system generates sentences from its processed sequence. section 1.6



























