A variational autoencoder (VAE) learns a latent space from which new images can be sampled. It also reconstructs inputs: an encoder maps an image into the latent space, and a decoder maps a latent point back to an image. Unlike a classical autoencoder, a VAE is designed to make that space continuous and structured, which is useful for image editing and interpolation. section 17.1.2 section 17.4
A two-dimensional space of handwritten digits
For MNIST, an encoder maps each 28 × 28 digit to two vectors, z_mean and z_log_var. A sampling layer uses them to choose a latent point; a decoder turns that point into a reconstructed digit. After training, decoding a grid of points across the two-dimensional space produces a grid of digits. section 17.1.3
Figure 17.4 A VAE maps an image to two vectors, z_mean and z_log_variance, which define a probability distribution over the latent space, used to sample a latent point to decode.
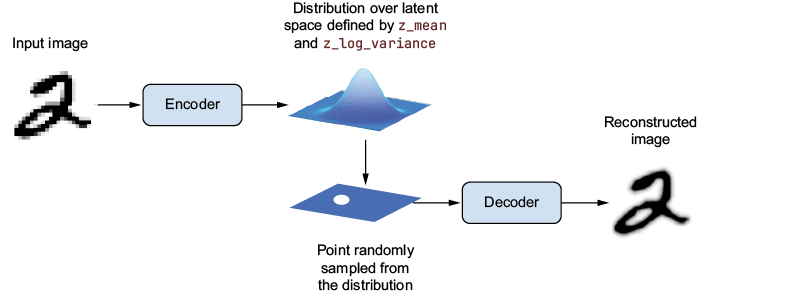
The diagram shows the crucial difference from a plain autoencoder: the encoder supplies parameters of a distribution, rather than one fixed code, before the decoder receives a sampled point. section 17.1.2
A practical Keras implementation has three parts:
- Encode images with a convolutional network that outputs z_mean and z_log_var. Strided convolutions preserve the location information needed for reconstruction. section 17.1.3
- Sample with a random epsilon using z_mean + exp(0.5 × z_log_var) × epsilon. section 17.1.3
- Decode the sampled vector into an image, and use custom training logic that tracks reconstruction and KL losses. Inputs themselves provide the reconstruction targets. section 17.1.3 section 17.1.2
Choose a VAE when reconstruction or control over a continuous latent space matters. For high-fidelity image generation, diffusion models are the stronger choice. section 17.1.2 section 17.4












