Suppose a recipe collection contains thousands of entries and someone asks, “How can I make lasagna?” Searching only for matching words may miss a relevant recipe phrased differently. An embedding is a numerical vector representation of text: it gives the question and recipes a form that can be compared for similarity. section 14.10.1 section 14.3
A small vector space
Imagine placing recipes on two scales: mild to spicy and savory to sweet. Each recipe becomes a point described by two numbers. A poke-bowl recipe could then be compared with stored recipes, with sushi emerging as a nearby match. Real recipe embeddings are generated from text rather than assigned flavor scores; the two-dimensional example makes the comparison visible. section 14.3
In a recipe retrieval workflow:
- Convert stored recipe text into embeddings and keep them in a vector database. An embedding model determines the numerical representation; text-embedding-3-large is one model used for this job. section 14.6.1
- Embed the user’s question with the same model used for the stored recipes, then run a vector similarity search to retrieve relevant documents. section 14.10.1
- For retrieval-augmented generation (RAG), combine the question with retrieved recipes and pass that context to a language model to generate an answer. Airflow can automate ingestion, chunking, embedding generation, and vector-database updates. section 14.3 section 14.11
Figure 14.17 In the retrieval workflow, we can embed a user’s question and perform a similarity search in the database using cosine similarity. The vector database returns the documents that are most relevant to the question.
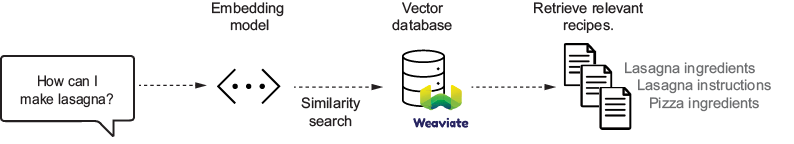
The retrieval diagram shows why both the stored documents and the incoming question need vector representations: similarity search compares them before returning relevant documents. section 14.10.1
Similarity depends on how vectors are compared. The flavor-space example first uses proximity to explain related recipes. For text, cosine similarity emphasizes vector direction rather than exact numerical values, helping compare recipes whose wording differs but whose meaning is similar. Vectors pointing in the same direction have cosine similarity of 1. section 14.10.1
Configure the embedding model
A Weaviate collection can receive its embedding setup through `vectorizer_config=[get_vectorizer_config(embedding_model)]`. The configuration function selects an OpenAI API or Azure OpenAI vectorizer according to `OPENAI_CONN_TYPE`; the collection-creation command supplies the model name. This keeps provider-specific settings out of the collection definition while making the model choice explicit. section 14.6.1














































